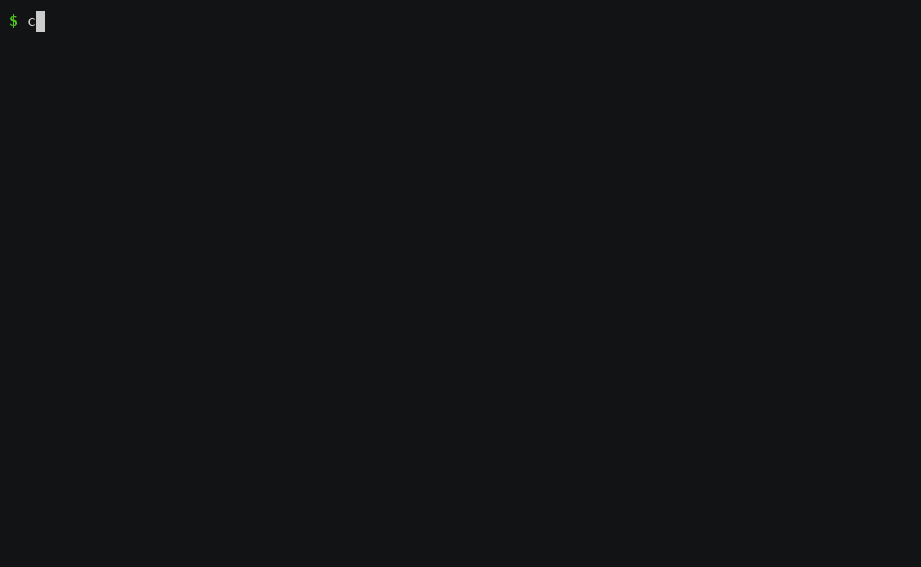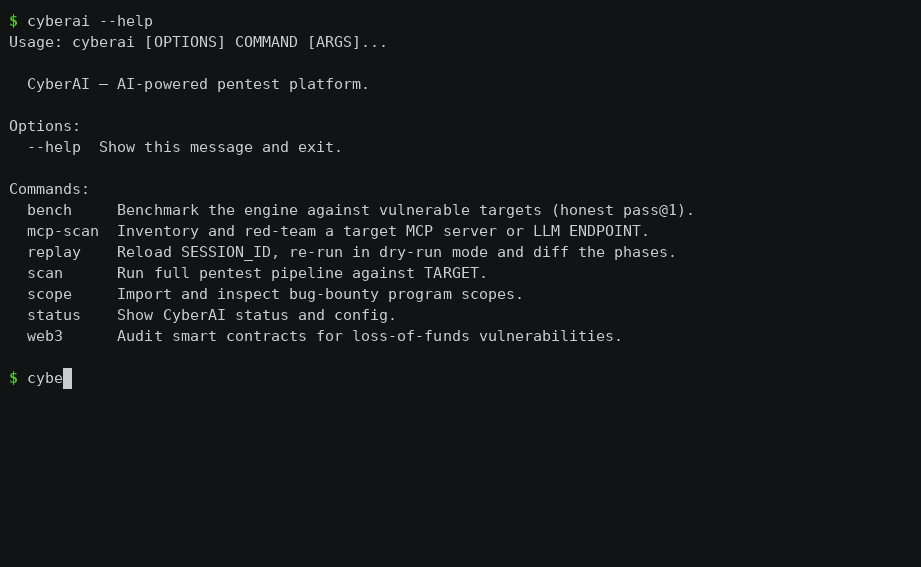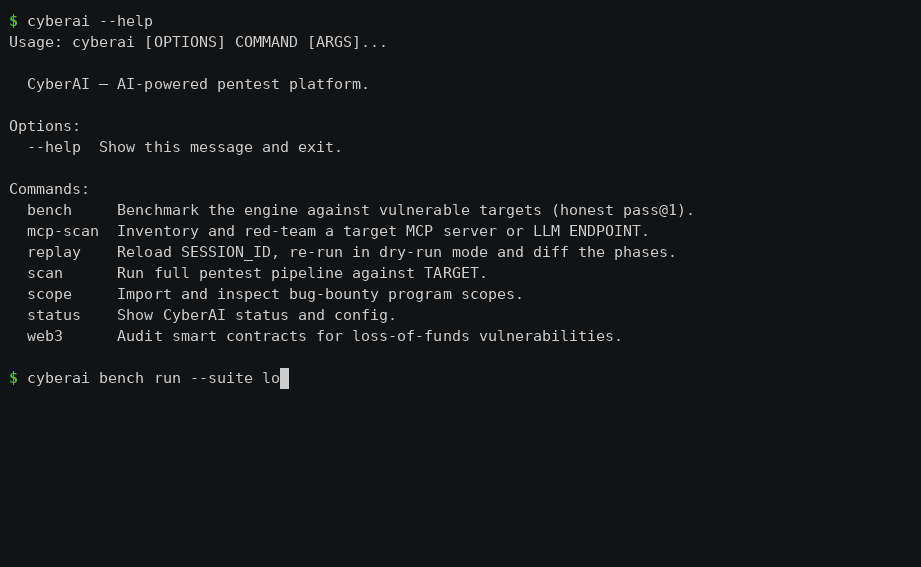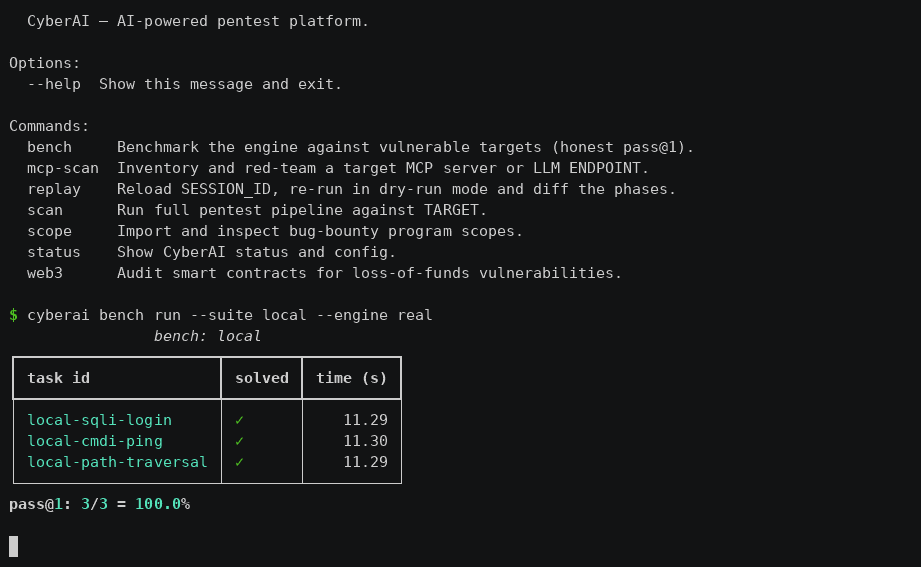
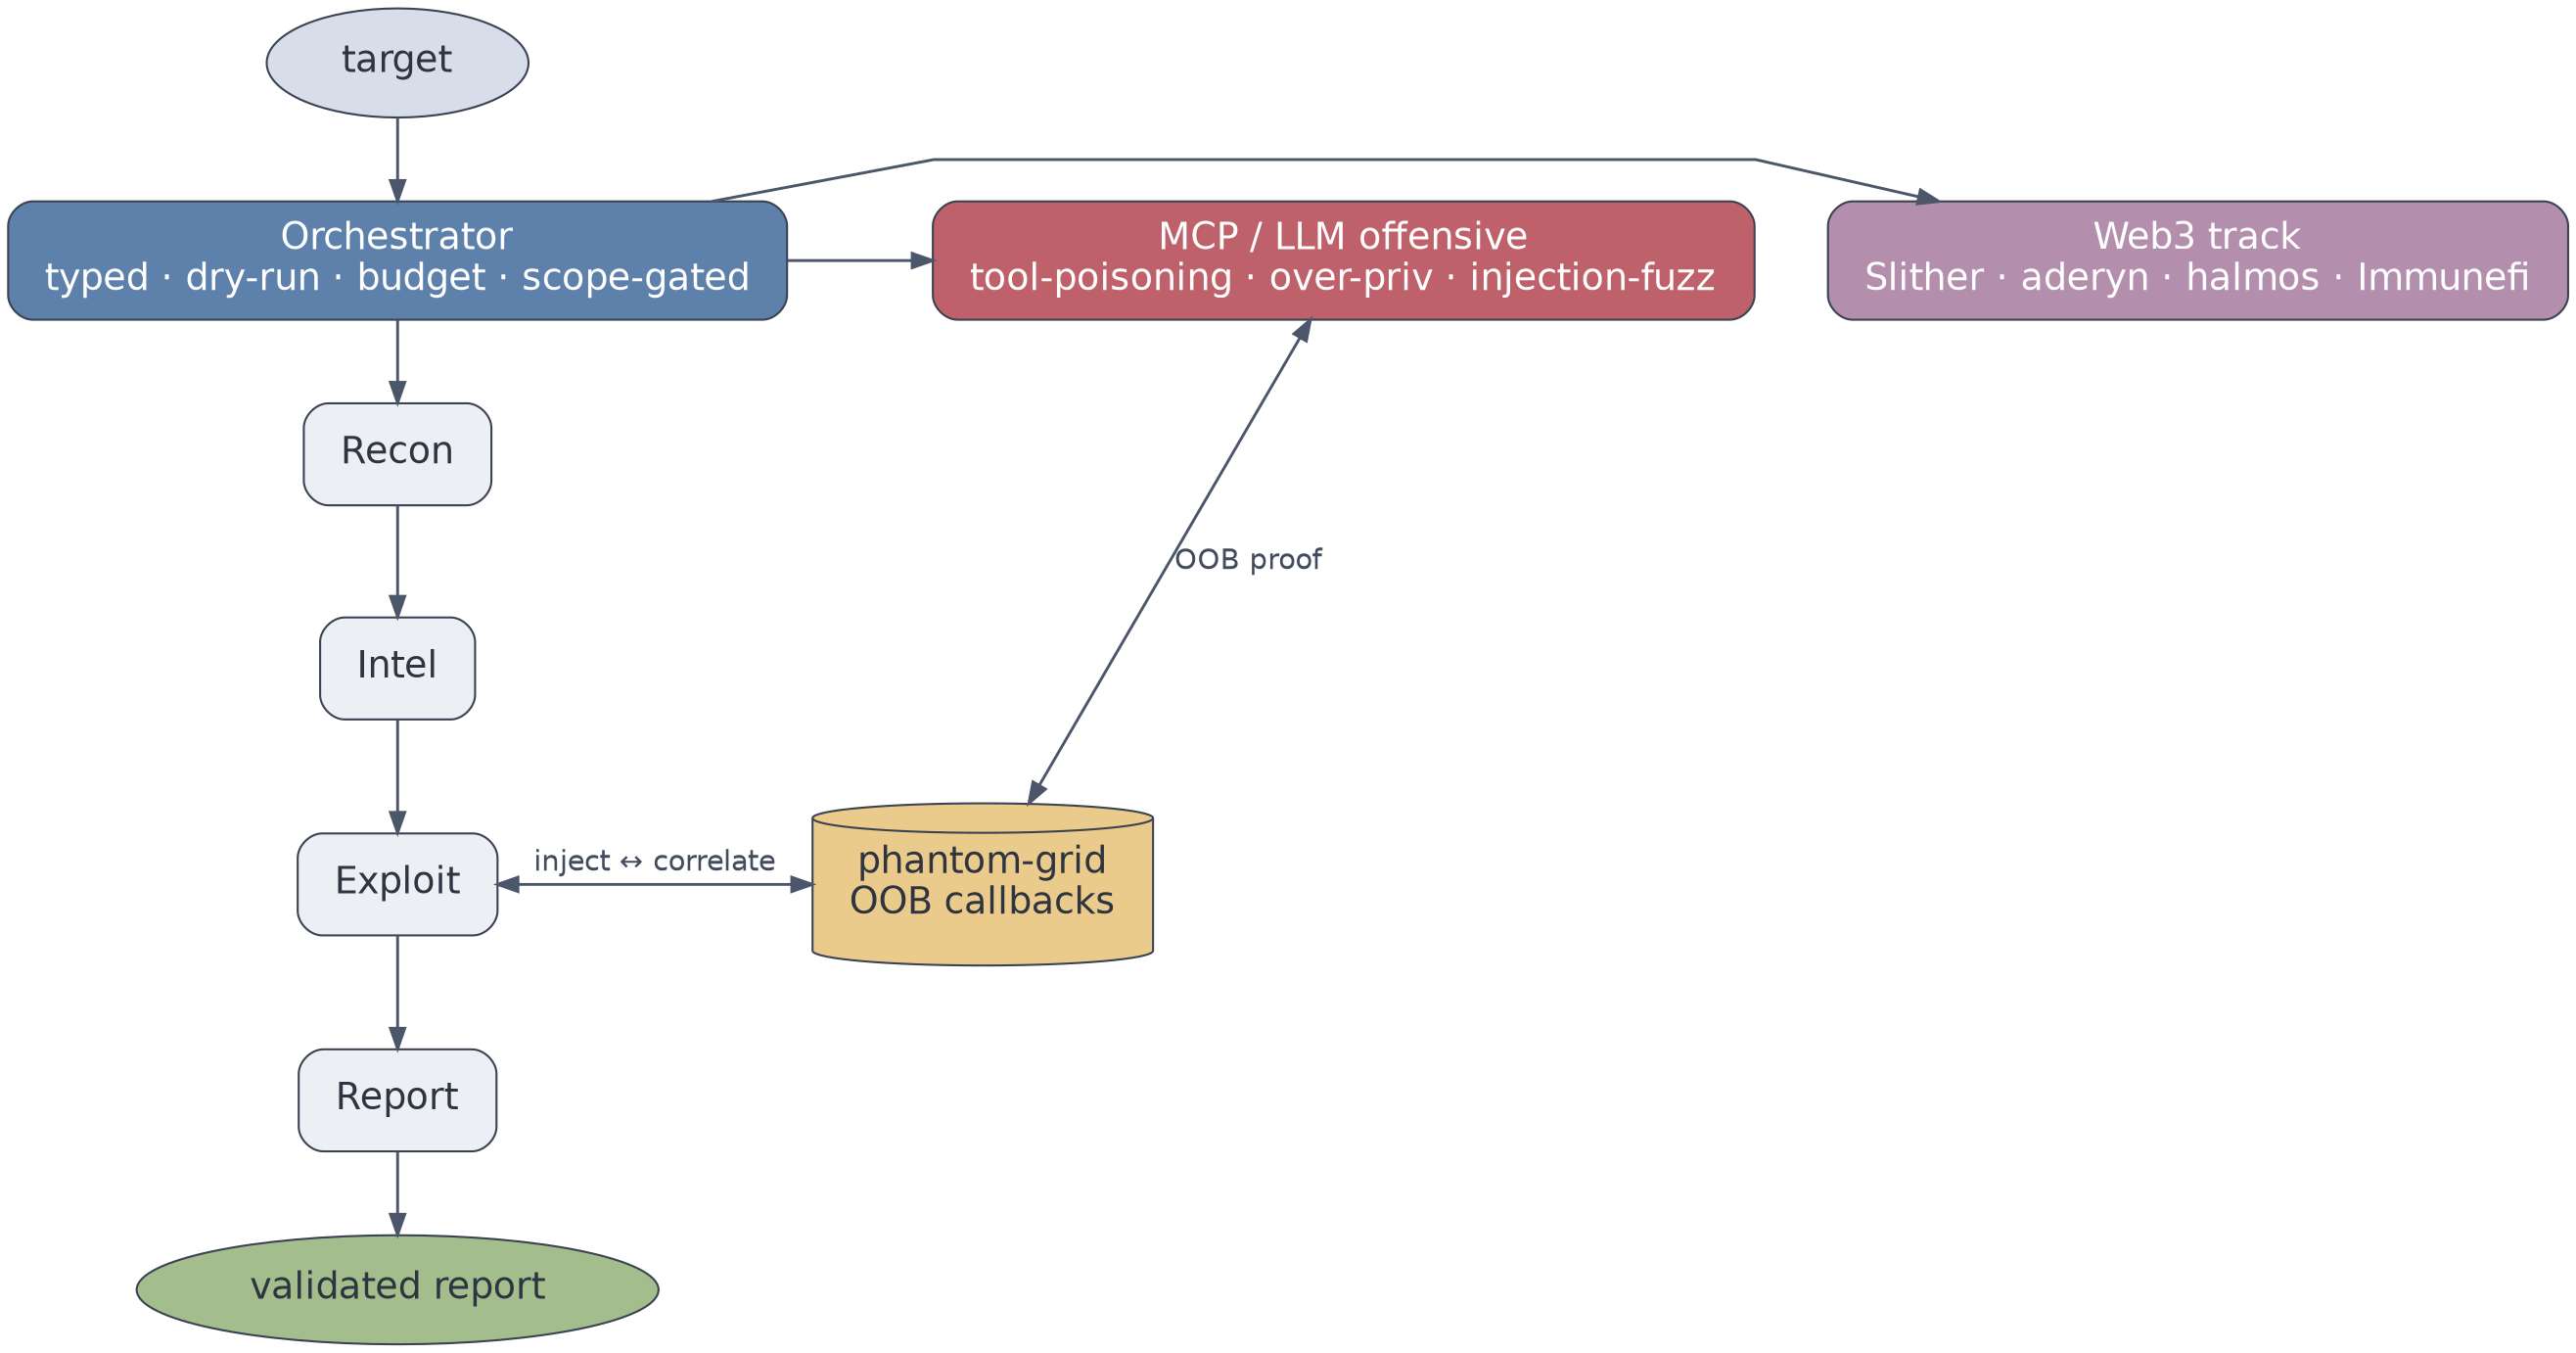
{"id":"6901e0f1-0bf5-4599-b6b7-a51377e58495","slug":"cyberai","kind":"mcp","name":"CyberAI","summary":"AI-powered pentest platform","owner":"evkir","repoUrl":"https://github.com/evkir/CyberAI","license":"Apache-2.0","licenseTier":"permissive","trust":"community","stars":2,"match":null,"fewStars":true,"format":"mcp","createdAt":"2026-04-13T08:34:36.000Z","addedAt":"2026-10-21T08:41:08.917Z","logoUrl":"https://avatars.githubusercontent.com/u/224408464?u=608ce324797e82af8700a42f3cf5d37230618626&v=4","linkOnly":false,"collection":null,"skillPath":null,"categories":["developer-tools","communication"],"tags":["ai-penetration-testing","ai-pentest","ai-pentesting","ai-tools","multi-agent","red-team","red-team-tools","ai-agents"],"runtime":"python","local":true,"cloudCapable":false,"cloudCapability":"unknown","cloudReadyOnPlatform":false,"needsApiKey":false,"reviewed":false,"syncedAt":"2026-10-26T17:31:00.395Z","sample":false,"url":"https://conduits.dev/tools/cyberai","language":"Python","transports":["stdio"],"install":{"pypi":"cyberai"},"requirements":{"env":[],"upstreamMayCharge":false},"tools":null,"readme":"<div align=\"center\">\n\n![CI](https://github.com/evkir/CyberAI/actions/workflows/ci.yml/badge.svg)\n![live recon](https://img.shields.io/endpoint?url=https://raw.githubusercontent.com/evkir/CyberAI/badges/latest.json)\n![Python](https://img.shields.io/badge/python-3.11%20%7C%203.12%20%7C%203.13%20%7C%203.14-blue)\n![License](https://img.shields.io/badge/license-Apache_2.0-blue)\n![Version](https://img.shields.io/badge/version-v1.7.0-brightgreen)\n![Tests](https://img.shields.io/badge/tests-3234%20collected-brightgreen)\n![Mypy](https://img.shields.io/badge/mypy-strict%3A%20117%2F175%20modules-blue)\n![LLM](https://img.shields.io/badge/LLM-OpenAI%20%7C%20Anthropic%20%7C%20Ollama-blueviolet)\n![Air-Gapped](https://img.shields.io/badge/air--gapped-ready-success)\n\n# 🤖 CyberAI\n\n**Metadata audit for MCP servers. Runtime red-team for LLM agents.**\n\n> For MCP servers it reads what the server declares — `initialize`,\n> instructions, tools, prompts, resources — and says which risk classes it\n> checks and which it does not:\n> [docs/redteam/mcp-scanning.md](docs/redteam/mcp-scanning.md). It does not\n> call a target's tools. A run against our own two servers, including the\n> CRITICAL it found on ours, is published in\n> [examples/mcp-audit/own-servers.md](examples/mcp-audit/own-servers.md).\n>\n> For LLM agents it is a live channel: injected canaries are proven\n> out-of-band, not inferred from response diffs.\n> Built by someone who red-teams AI, not just with it.\n\n![CyberAI benchmark demo](https://raw.githubusercontent.com/evkir/CyberAI/main/docs/assets/demo-bench.gif)\n\n*Recorded run of the fixed probes against four vulnerable targets in Docker — pass@1 4/4, which says the targets and the harness work. The pipeline itself scores the same suite 4/4 in 21 requests; both cards are linked below. The fourth target is blind: it counts as solved only when a collector we control records the callback. Reproduce with `cyberai bench run --suite local --engine real`.*\n\n</div>\n\n---\n\n## What is CyberAI?\n\n**The target is the AI supply chain.** An MCP server, an LLM endpoint, a RAG\npipeline, a smart contract — surfaces where the attack is carried by text a\nmodel trusts, and where a port scanner has nothing to say. CyberAI reads what\nan MCP server declares and names which risk classes it checks and which it\ndoes not; it sends live payloads at agent endpoints; it audits contracts\non-chain. Hosts and ports are one surface it also covers, not the premise.\n\nTwo commitments hold the rest up:\n\n- **Nothing is reported on a hunch.** Blind vulnerabilities — SSRF, XXE, blind\n  injection — count as found when an out-of-band callback reaches a collector\n  we control, captured by\n  [phantom-grid](https://github.com/evkir/phantom-grid). A response diff that\n  looks suggestive is not a finding.\n- **The model is treated as attackable.** Every message on its way to a model\n  passes one guard, which labels or blocks what scores as an injection before\n  the provider is contacted; each phase's output is separately scanned and a\n  hit becomes a MEDIUM finding. The gaps are named rather than implied, in\n  [docs/security/adversarial-robustness.md](docs/security/adversarial-robustness.md).\n\nThe machinery underneath. Eight specialized agents run a typed, auditable\npipeline. **MCP Scan**, **Redteam** and **Web3** take their own kinds of\ntarget; **Recon, Intel, Exploit, Report** form the network chain; **Planner**\norders the work the others do. The table below says what each one takes and\nproduces.\n\nReal orchestrator output (trust-aware pipeline in action):\n\n```text\n⚠ injection signals in recon output (risk=25)\n[ExploitAgent] Generating OOB payloads...\n[ExploitAgent] Polling phantom-grid...\n[exploit] OOB callbacks: 1\n```\n\n\n## Quick Start\n\n```bash\npip install cyberai\n\n# dry-run: full pipeline, no real network calls\ncyberai scan example.com --dry-run\n\n# real scan with a local model (air-gapped, no cloud) and scope\ncyberai scan app.target.com --provider ollama --scope \"*.target.com\"\n\ncyberai status          # provider, output, trust boundary, sampling, air-gap, credentials, toolchain, run controls\ncyberai replay <id>     # re-run a saved session\n```\n\n**See it on a real target:** a full run against OWASP Juice Shop, committed\nexactly as produced — 14 endpoints found, 13 walked, one SQL injection proven\nby the database error it returned, and the local model's reading of all of it,\nincluding the 15 parameters that ignored every payload and the 10 that\nrefused the caller outright:\n[examples/juice-shop/](examples/juice-shop/)\n\n**Trust-aware in one sentence:** a malicious banner crafted to hijack the model\nis wrapped as untrusted where it is stored, and if it ever reaches a prompt the\nguard in front of the provider labels, redacts or blocks it — under `deny`, no\nrequest is made at all. Recon and intel contact no model, so a banner from those\nphases reaches one only by way of the report.\n\n\n---\n\n## Architecture\n\n![CyberAI architecture](https://raw.githubusercontent.com/evkir/CyberAI/main/docs/assets/architecture.png)\n\n<details><summary>Diagram source (Mermaid, rendered on GitHub)</summary>\n\n```mermaid\nflowchart LR\n    T([target]) --> O[Orchestrator<br/>typed · dry-run · budget · scope-gated]\n    O --> R[Recon] --> I[Intel] --> E[Exploit] --> RP[Report] --> V([validated report])\n    E <-->|inject ↔ correlate| PG[(phantom-grid<br/>OOB callbacks)]\n    O --> W3[Web3 track<br/>Slither · aderyn · halmos · Immunefi]\n    O --> MCP[MCP / LLM offensive<br/>tool-poisoning · over-priv · injection-fuzz]\n    MCP <-->|OOB proof| PG\n```\n\n</details>\n\n> **Trust boundary** — one guard inside `LLMClient`, ahead of every provider\n> call; phase edges are audited on top of it, in both pipelines.\n> Findings reach **confidence = 1.0 only when confirmed out-of-band** via phantom-grid.\n\n**Observability:** JSONL audit log · session export/import · `cyberai replay`\n**Interfaces:** CLI · FastAPI dashboard (SSE) · MCP server (Claude Desktop)\n\n### Agents\n\n| Agent | Input | Output | Key tools |\n|-------|-------|--------|-----------|\n| **Recon** | target | open ports, DNS, WHOIS, subdomains | nmap (flag-whitelisted), async DNS, subdomain enum |\n| **Intel** | recon kb | ranked CVEs | NVD client, EPSS enrichment, risk prioritizer |\n| **Exploit** | intel kb | attack paths, OOB findings | nuclei, searchsploit, OOB/SSRF/XXE workflows |\n| **Report** | session kb | structured Markdown / H1 export | LLM summary + LLM-as-judge validation |\n| **Web3** | .sol path / address | severity-tiered findings | Slither, Etherscan, Immunefi classifier |\n| **Planner** | kb relationship graph | ordered subtask plan | deterministic ranking, critic that decides retry vs skip |\n| **MCP Scan** | MCP endpoint (stdio or HTTP/SSE) | capability surface, poisoning and over-privilege findings | live probe, attestation posture, MST bridge |\n| **Redteam** | LLM or RAG channel | injection fuzz report | payload corpus, channel fuzzer, acknowledgement detection |\n\n---\n\n## What's shipped / what's next\n\nCyberAI is an actively developed platform, not a scaffold. Shipped and tagged:\n\n| Version | Focus | Highlights |\n|---|---|---|\n| **v1.0** | Core platform | typed 4-phase pipeline, OOB exploitation, Web3 (Slither/Immunefi), MCP server, LLM-as-judge, scope import, async, cost tracking |\n| **v1.1** | Proof & benchmarks | reproducible bench harness + local vuln suite, honest scorecard, per-phase model router, air-gapped path (egress guard) |\n| **v1.2** | MCP audit and LLM red-team | MCP probe + scan CLI, tool-poisoning & over-privilege detectors, live injection fuzzer, attestation checks, MST bridge |\n| **v1.3** | Web3 discovery | aderyn cross-validation, halmos symbolic runner, Foundry on-chain PoC, access-control agent, EVMBench adapter, Immunefi export |\n| **v1.4** | Autonomy & unified reporting | graph planner driving exploit order, exploit-memory recall, unified OOB confirmation, behavioral fingerprinting, findings grouped by attack surface |\n| **v1.5** | The HTTP surface | API-spec and JS-bundle route discovery, authenticated walks, object-level authorization checks, out-of-band confirmation on the product path |\n| **v1.6** | Honest release | one trust boundary in front of the model with three policies, decontaminated proofs, the agent score published, Apache-2.0 |\n| **v1.7** | Refusal by default | an unscoped run refuses the exploit phase (breaking), the regression gate reads the toolchain it recorded, a benchmark record no longer pulls the probe that fills it |\n\n**Next:** wider public proof — benchmark re-runs published as a tracked delta, sample reports for each attack surface, and reproducible live runs.\n\n---\n\n## Security design\n\n- **One trust boundary in front of the model** — `TrustGuard.inspect()` sits\n  inside `LLMClient`, ahead of the provider branch, on all four entry points.\n  Nothing reaches OpenAI, Anthropic or Ollama without passing it. It scores\n  the raw message and sanitises the copy it sends: the reverse order was\n  measured to blind the detector, because sanitisation strips three of the\n  categories the detector scores on, so a payload carrying a template marker\n  scored *lower* through the guard than raw. System prompts are never\n  rewritten — only user, tool and function messages are attacker-reachable.\n- **Three policies, one variable** — `CYBERAI_INJECTION_POLICY` selects\n  `annotate` (default: label the content as untrusted, send it, record the\n  verdict), `quarantine` (label, replace each match with\n  `[REDACTED:<category>]`, cap the length), or `deny` (raise; the provider is\n  never contacted). Pick `annotate` when a false positive must not corrupt\n  legitimate input, `deny` for an engagement where a suspected injection\n  should stop the run. `quarantine` is not the default on purpose: it mutates\n  content, and the detector it would run on has no published precision. The\n  figure behind that choice — 42 flagged of 43 real scan reports — was taken\n  on a corpus that is not tracked in this repository and no longer exists. It\n  is kept in `core/security/guard.py` as the recorded reason for the default,\n  not as a reproducible measurement. `quarantine` becomes the default when W3\n  publishes precision and recall on a tracked corpus.\n- **Every verdict is in the audit trail** — policy, threshold, score,\n  categories and how many messages were modified, written per call. Message\n  bodies stay out of it.\n- **Prompt-injection detection** — 33 patterns across 10 weighted categories,\n  measured rather than described. On the tracked corpus the pattern layer\n  scores 58.2% recall at 100.0% precision with a 0.0% false-positive rate,\n  and it is blind to four injection subclasses: multilingual, paraphrase,\n  social, stative. The optional local-model layer takes recall to 90.9% and\n  costs precision to do it: 92.6%, at a 3.8% false-positive rate, all of it\n  on server descriptions written to address an assistant. Neither number is typed by hand — both come\n  out of `cyberai detector eval --corpus tests/corpus`, the second with\n  `--l2-replay examples/detector-eval/l2-verdicts.json`, and a test fails if\n  this paragraph and that command disagree. Also run\n  on each phase's *output*, where a hit becomes a MEDIUM finding. That pass\n  is an audit signal, not a barrier: it runs after the agent has already\n  called the model, and it is labelled as such in the code and the report.\n  The barrier is the guard above.\n- **Scope enforcement** — wildcard + `!`-exclusion matching honors HackerOne /\n  Bugcrowd briefs (`cyberai scope import`).\n- **Audit trail** — every agent action logged to JSONL with full\n  inputs/outputs; sessions are replayable. Every line is HMAC-signed —\n  `cyberai audit-verify <file>` reports any line edited after the run.\n\n---\n\n## Install from source\n\n```bash\ngit clone https://github.com/evkir/CyberAI.git\ncd CyberAI\npip install -e .\n```\n\n```bash\ncp config.example.yml config.yml\ncp .env.example .env\n# Edit .env — add OPENAI_API_KEY or ANTHROPIC_API_KEY (not needed for --dry-run)\n```\n\n```bash\n# Dry-run: walks all 4 phases, no network, no API key\npython -m cyberai scan example.com --dry-run\n\n# Real scan, scope-restricted\npython -m cyberai scan target.htb --scope '*.target.htb'\n\n# Replay a saved session deterministically\npython -m cyberai replay <session_id>\n\n# Import a bug-bounty scope\npython -m cyberai scope import h1 --program acme\n\n# Status / config\npython -m cyberai status\n```\n\n### Web dashboard\n\n```bash\nuvicorn cyberai.web.app:app --reload\n# http://127.0.0.1:8000  — session list, live SSE progress, report view\n```\n\n### MCP server (Claude Desktop / Cursor)\n\n```bash\npython -m cyberai.mcp.server\n```\n\nExposes recon/intel tools (`nmap_scan`, `dns_enum`, `cve_search`,\n`epss_score`, …) plus `mcp_scan` — which lets the server scan *other* MCP\nservers — over the Model Context Protocol. See\n[docs/mcp/integration.md](docs/mcp/integration.md).\n\n### MCP / LLM offensive red-team\n\n```bash\ncyberai mcp-scan http://target.example.com/mcp --report\n```\n\nInventory a target MCP server or LLM endpoint and emit an OWASP-MCP /\nMITRE-ATLAS red-team report. See\n[docs/redteam/mcp-scanning.md](docs/redteam/mcp-scanning.md).\n\n---\n\n## Configuration\n\n```yaml\n# config.yml\nllm:\n  provider: openai        # openai | anthropic | ollama\n  model: gpt-4o\n  max_tokens: 4096\n  temperature: 0.2\n\nphantom:\n  grid_url: http://127.0.0.1:9090\n\noutput_dir: reports/\nmax_cost_usd: 0.0         # 0 = disabled; set to enforce a budget\n```\n\n### Environment variables\n\nEvery setting can be driven from the environment (or a `.env` file - see\n[.env.example](.env.example)). Feature flags are off by default\n(no-regression); enable any with `1`/`true`/`yes`/`on`.\n\n| Variable | Effect |\n|---|---|\n| `CYBERAI_LLM_PROVIDER` / `CYBERAI_MODEL` | LLM provider and model. The provider is one of `openai`, `anthropic`, `ollama`; any other value is nobody having chosen one, so the default stands and the run is not aborted -- `cyberai status` prints the provider actually in force. `--provider` is stricter: the parser refuses an unknown name and lists the ones that exist |\n| `CYBERAI_USE_BEHAVIORAL` | Honeypot/WAF/tarpit fingerprinting in recon |\n| `CYBERAI_USE_PORT_FINGERPRINT` | Banner grab on ports nmap could not name |\n| `CYBERAI_USE_NUCLEI` | Nuclei template exploit engine |\n| `CYBERAI_USE_JUDGE` | LLM-as-Judge report validation |\n| `CYBERAI_ENABLE_REPLAN` | Critic-driven phase replan |\n| `CYBERAI_USE_EXPLOIT_MEMORY` | Recall similar past exploit chains |\n| `CYBERAI_AIR_GAPPED` | Force local-only (no-egress) LLM path |\n| `CYBERAI_STRICT_SCOPE` | Refuse an unauthorised run before the first phase (default on; `0`, `false`, `no`, `off` or `--no-strict-scope` to opt out -- any other value leaves the refusal on) |\n| `CYBERAI_ENABLE_MODEL_ROUTING` | Per-phase model selection |\n| `CYBERAI_MAX_COST_USD` | LLM spend budget (0 = disabled) |\n| `CYBERAI_OUTPUT_DIR` | Report output directory |\n| `CYBERAI_SESSION_SECRET` | Audit-trail signing key; unset means a published fallback |\n| `CYBERAI_LOG_LEVEL` | Level for the package logger: `DEBUG`, `INFO`, `WARNING`, `ERROR`. Unset, the package logs nothing below a warning, which hides the calls reporting that a check was skipped rather than passed. A value that is not a level leaves logging untouched rather than aborting the run |\n\nThe `scan` command overrides the main flags per run, in either direction:\n\n```bash\ncyberai scan example.com --behavioral --nuclei\ncyberai scan example.com --no-air-gapped\n```\n\n\n---\n\n## Benchmarks — honest numbers\n\nCyberAI measures its own engine against a small, self-contained suite of\ndeliberately-vulnerable targets it authors and serves — no third-party\nbenchmark required to reproduce the numbers.\n\n```bash\ncyberai bench list\ncyberai bench run --suite local --engine agent --scorecard reports/scorecard-agent.md\ncyberai bench run --suite local --engine real  --scorecard reports/scorecard.md\n```\n\nEvery published number is **reproducible** (targets ship in `cyberai/bench/apps/`),\n**binary** (solved only on an unambiguous success signal from a responding\ntarget — never \"looks exploited\"), and **traceable** (each run emits a scorecard\nwith engine version, provider, model, timestamp).\n\nLatest run of the local suite (CyberAI 1.6.0, 2026-08-26), scored twice — once by the pipeline that is the product, once by the fixed probes. Both reach 4/4:\n\n| vuln class | solved | total | rate |\n| --- | --- | --- | --- |\n| sqli | 1 | 1 | 100% |\n| command_injection | 1 | 1 | 100% |\n| path_traversal | 1 | 1 | 100% |\n| ssrf | 1 | 1 | 100% |\n| **pass@1** | **4** | **4** | **100%** |\n\nWhat the pipeline spent reaching that score. The probes produce none of these\nnumbers, which is why the card beside this one has no metrics section:\n\n| task id | in-band | out of band | endpoints | requests |\n| --- | --- | --- | --- | --- |\n| local-sqli-login | 2 | 0 | 1 | 5 |\n| local-cmdi-ping | 1 | 0 | 1 | 3 |\n| local-path-traversal | 1 | 0 | 1 | 3 |\n| local-ssrf-fetch | 0 | 1 | 1 | 10 |\n| **total** | **4** | **1** | **4** | **21** |\n\nTwo engines, one suite, answering different questions. `--engine real` drives\nfixed per-class probes: 4/4 there means the targets are exploitable and the\nharness works — it measures the bench, not the product. `--engine agent`\ndrives the full pipeline, which is handed an address and has to discover the\nsurface before it can attack it; 4/4 there is the product finding and proving\nfour flaws on its own. The second is the number worth publishing, and it is\nthe one above.\n\nRead the zero honestly: **the pipeline reaches 4/4 without contacting a\nmodel.** The agent engine constructs no LLM client on this path, and the card\nrecords that rather than implying it — `llm calls 0`, `llm zero reason\nengine_uses_no_model`, a proven zero instead of a blank nobody counted.\nDiscovery, payload selection and proof are code here, not inference. The\nmodel earns its place elsewhere: reading a surface larger than four\nendpoints, the analysis and the report. Publishing this suite as evidence of\na language model solving CTFs would be the easy lie — it solved them with no\nmodel at all.\n\nIn-band and out-of-band are counted apart because of the blind SSRF target:\nit answers identically whichever way the fetch goes, so it is proven by a\ncallback carrying the run nonce, and folding that into the in-band column\nwould print a zero on a task that was solved.\n\nRead the suite honestly too: it is **authored by the project it measures**.\nIt proves the engine works end-to-end against live targets in Docker and\nguards against regression between releases — it is not a competitive result\nand is not comparable to CVE-Bench or CyBench. The one external suite run so\nfar, CVE-Bench, scored 0/3 on three selected tasks; the runs and the reason\nare in [docs/benchmarks/cve-bench.md](docs/benchmarks/cve-bench.md).\n\nPart of an earlier 4/4 was self-referential — the exploitation engine held a\nliteral from a target this project wrote. What was wrong, what changed and\nwhat the numbers did afterwards is written up in\n[docs/benchmarks/contamination-2026-08.md](docs/benchmarks/contamination-2026-08.md).\n\nBoth cards are committed:\n[scorecard-agent.md](examples/local-bench/scorecard-agent.md) for the\npipeline, [scorecard.md](examples/local-bench/scorecard.md) for the probes.\nThe run manifest is not, and `--manifest <path>` reproduces it.\n\nThe default `--engine placeholder` reports all-unsolved by design so a scorecard\nnever overstates capability; `--engine real` runs live per-class probes. External\nsuites (CVE-Bench, CyBench, EVMBench) plug into the same `BenchTask` contract as\noptional adapters for leaderboard parity — never as a product dependency.\n\nSee [docs/benchmarks/local-suite.md](docs/benchmarks/local-suite.md) for the\nmethodology and the current scorecard.\n\n---\n\n## Documentation\n\n| Doc | What |\n|-----|------|\n| [docs/api/agents.md](docs/api/agents.md) | Agent API reference |\n| [docs/exploit/oob-exploitation-workflow.md](docs/exploit/oob-exploitation-workflow.md) | OOB / SSRF walkthrough |\n| [docs/web3/web3-audit.md](docs/web3/web3-audit.md) | Smart-contract audit for Immunefi |\n| [docs/mcp/integration.md](docs/mcp/integration.md) | MCP server setup |\n| [docs/redteam/mcp-scanning.md](docs/redteam/mcp-scanning.md) | MCP/LLM offensive red-team scanning |\n| [docs/security/adversarial-robustness.md](docs/security/adversarial-robustness.md) | What the trust boundary covers, and what it does not |\n| [docs/research/detector-v2.md](docs/research/detector-v2.md) | The three detector layers, what each was measured at, and what was not measured |\n| [examples/detector-eval/baseline.md](examples/detector-eval/baseline.md) | Detector precision and recall on the tracked corpus, per technique |\n| [examples/mcp-audit/own-servers.md](examples/mcp-audit/own-servers.md) | An MCP audit run against our own two servers, including the CRITICAL on ours |\n| [docs/benchmarks/local-suite.md](docs/benchmarks/local-suite.md) | The local suite: targets, success signals, methodology |\n| [docs/benchmarks/reproducibility.md](docs/benchmarks/reproducibility.md) | What a run pins, what it records, what it cannot promise |\n| [docs/benchmarks/contamination-2026-08.md](docs/benchmarks/contamination-2026-08.md) | A self-referential proof, how it was found, what the numbers did |\n| [docs/benchmarks/cve-bench.md](docs/benchmarks/cve-bench.md) | The external suite, scored 0/3, with the cause |\n| [docs/architecture/risk-register.md](docs/architecture/risk-register.md) | Twenty-two risks to the project, each with a status and the test that holds it |\n| [docs/architecture/typing-scope.md](docs/architecture/typing-scope.md) | What the type checker reads, what it does not, and why |\n| [docs/architecture/refusal.md](docs/architecture/refusal.md) | Every way the tool says no, and why one reader narrows where another refuses |\n| [docs/workflows/htb-with-cyberai.md](docs/workflows/htb-with-cyberai.md) | Walkthrough: a lab box end to end |\n| [docs/workflows/web3-discovery.md](docs/workflows/web3-discovery.md) | Walkthrough: contract discovery to Immunefi export |\n| [docs/usage/examples.md](docs/usage/examples.md) | Command recipes by task |\n| [docs/setup/nvd-apikey.md](docs/setup/nvd-apikey.md) | NVD API key setup for CVE lookup |\n| [docs/licensing.md](docs/licensing.md) | Apache-2.0, the CLA, and the planned transfer to the LLC |\n\n---\n\n## Related tools\n\n| Tool | Role |\n|------|------|\n| [phantom-grid](https://github.com/evkir/phantom-grid) | OOB interaction capture |\n| [phantom-intel](https://github.com/evkir/phantom-intel) | CVE intelligence feed |\n| [reality-probe](https://github.com/evkir/reality-probe) | TLS front fitness scoring (standalone) |\n\n---\n\n## Requirements\n\n- Python 3.11-3.14 (all four run in CI)\n- OpenAI **or** Anthropic API key (not required for `--dry-run`)\n- Optional: phantom-grid (OOB), nuclei, slither, NVD API key\n\n## ⚠️ Legal / Authorized Use\n\nCyberAI is an offensive-security tool intended **strictly for authorized\nsecurity testing, research, and education**. Use it **only** against systems\nyou own or for which you hold explicit, written permission (e.g. a signed\nengagement, an in-scope bug-bounty program, or a lab you control).\n\n- Unauthorized scanning, exploitation, or access of systems is illegal in most\n  jurisdictions and is **not** condoned by this project.\n- You are solely responsible for ensuring your use complies with all applicable\n  laws and with the rules of any target program.\n- The software is provided \"as is\", without warranty of any kind. The authors\n  and contributors accept **no liability** for misuse or for any damage arising\n  from its use.\n\nBy using CyberAI you agree to operate within these bounds.\n\n---\n\n\n---\n\n## License\n\nApache-2.0 — see [LICENSE](LICENSE) and [NOTICE](NOTICE).\n\nReleases up to and including v1.5.0 were published under MIT and remain\navailable under those terms. Contributions require a signed\n[CLA](CLA.md); the reasoning is in [docs/licensing.md](docs/licensing.md).\n\n<div align=\"center\">\n<sub>Part of the <a href=\"https://github.com/evkir\">evkir</a> security toolchain.</sub>\n</div>\n"}