{"id":"1fc7cc99-484a-4ec3-81c1-7ca17cb0de15","slug":"great-generator","kind":"skill","name":"great-generator","summary":"Generate realistic Synthetic enterprise data for Spark, Pandas, testing, demos, benchmarking, learning, and research.","owner":"GreatDataLabs","repoUrl":"https://github.com/GreatDataLabs/great-generator","license":"MIT","licenseTier":"permissive","trust":"community","stars":69,"match":null,"fewStars":false,"format":"skill","createdAt":"2026-05-17T20:57:32.000Z","addedAt":"2026-10-21T17:22:56.587Z","logoUrl":"https://avatars.githubusercontent.com/u/329800136?v=4","linkOnly":false,"collection":null,"skillPath":null,"categories":["data-analytics","developer-tools"],"tags":["benchmarking","data-engineering","data-generation","data-generator","etl-testing","faker","pandas","pyspark"],"runtime":"python","local":true,"cloudCapable":false,"cloudCapability":"unknown","cloudReadyOnPlatform":false,"needsApiKey":false,"reviewed":false,"syncedAt":"2026-10-25T14:46:10.187Z","sample":false,"url":"https://conduits.dev/tools/great-generator","language":"Python","transports":["stdio"],"install":{"pypi":"great-generator"},"requirements":{"env":[],"upstreamMayCharge":false},"tools":null,"readme":"# Great Generator\n\n
\n \n
\n\n\n[](https://github.com/GreatDataLabs/great-generator/actions/workflows/tests.yml)\n[](https://pypi.org/project/great-generator/)\n[](https://pypi.org/project/great-generator/)\n[](https://pypi.org/project/great-generator/)\n[](LICENSE)\n[](https://github.com/GreatDataLabs/great-generator/stargazers)\n[](https://github.com/GreatDataLabs/great-generator/issues)\n[](CONTRIBUTING.md)\n\n## Generate Realistic Synthetic Data from Your Schema\n\n**Have a schema but no safe test data?**\n\nUse Great Generator to create realistic, synthetic, non-production data directly from your schema for development, QA, SIT, UAT, sandboxes, ETL validation, analytics, demos, and data engineering workflows.\n\n```python\nfrom great_generator import generate_from_schema\n\nschema = {\n \"customer_id\": \"string\",\n \"customer_name\": \"string\",\n \"age\": \"int\",\n \"email\": \"string\",\n \"address\": \"string\",\n \"city\": \"string\",\n \"state\": \"string\",\n \"created_at\": \"datetime\",\n \"account_status\": \"string\",\n}\n\ndf = generate_from_schema(schema=schema, rows=1000)\n\nprint(df.head())\n```\n\nGreat Generator is built for teams that already know their schema but cannot use production data in lower environments.\n\n> Great Generator creates synthetic data. It does not anonymize, mask, de-identify, or transform production records. Always follow your organization's privacy, security, governance, and compliance policies.\n\n## Architecture at a Glance\n\n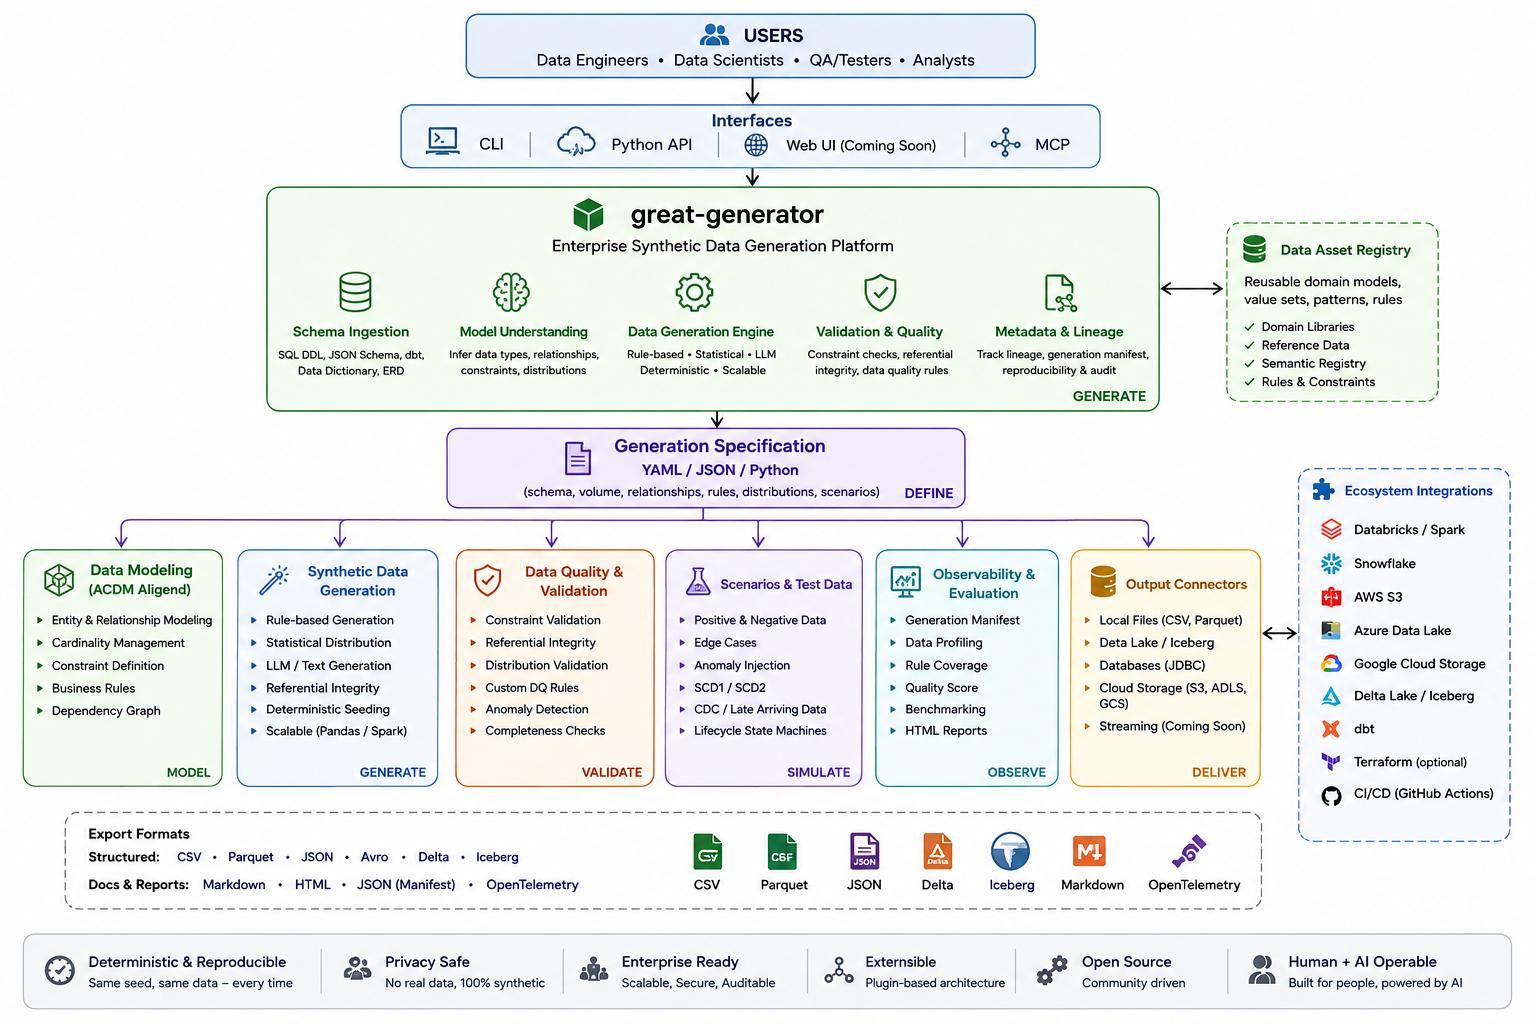\n\nGreat Generator is designed as a schema-first synthetic data platform: ingest schemas and metadata, understand fields and relationships, generate deterministic synthetic data, validate quality, and deliver DataFrames or files into the tools your team already uses.\n\n## Problem Statement\n\nReal projects need production-like data outside production. Copying production records into development, QA, SIT, UAT, sandbox, demo, or performance-testing environments is often restricted because of privacy, security, PII, PHI, PCI, internal policy, or data governance concerns.\n\nTeams still need realistic data to:\n\n- test ingestion and transformation pipelines\n- validate schemas, joins, and business rules\n- exercise APIs and application services\n- build dashboards and analytics models\n- test data quality controls and failure paths\n- run demonstrations, prototypes, and performance checks\n- onboard developers without sharing sensitive records\n\nGreat Generator turns table-like schema definitions into usable Pandas or Spark DataFrames. You keep control of where those DataFrames are written.\n\n## Why Schema-Based Synthetic Data Matters\n\nMost engineering teams do not begin with a blank domain. They already have a contract: column names, data types, a DataFrame, a Spark schema, or a table definition. `generate_from_schema` uses that contract and semantic field inference to generate values that are more useful than type-correct placeholders.\n\nFor example, these fields are recognized as name-like fields rather than generic strings:\n\n- `customer_name`\n- `cust_name`\n- `employee_name`\n- `emp_name`\n- `member_name`\n- `patient_name`\n\nThe same semantic layer recognizes IDs, email addresses, phone numbers, addresses, ages, dates, monetary values, quantities, statuses, and common lifecycle relationships.\n\n## Who This Library Is For\n\n- **Data engineers** testing ETL, ELT, Spark, Delta, and lakehouse pipelines\n- **QA engineers** creating repeatable positive, negative, and edge-case datasets\n- **Application developers** testing APIs, databases, and integration contracts\n- **Analytics engineers** validating models, joins, dashboards, and SQL transformations\n- **Platform teams** provisioning safe lower-environment datasets\n- **Performance engineers** creating environment-appropriate volume tests\n- **Researchers and ML engineers** building reproducible prototypes without production records\n- **Students, speakers, and educators** using ready-made domain packs for learning and demos\n\n## What You Can Do\n\n- generate a realistic DataFrame from a schema\n- use plain Python mappings, Pandas schemas, compact DDL, SQL DDL, JSON Schema, dbt metadata, data dictionaries, or PySpark schemas\n- apply per-column ranges, categories, prefixes, patterns, weights, date windows, and null rates\n- inspect the semantic generation plan before generating data\n- validate generated values and cross-field consistency\n- generate query-aware data with required values, partition dates, selectivity, and join coverage\n- compile supported SQL workloads into deterministic predicate, join, NULL, and boundary witnesses with measurable coverage\n- inspect permitted Databricks Unity Catalog metadata and generate single or related synthetic tables without reading source records\n- return Pandas or Spark DataFrames for downstream writes\n- generate custom relational parent-child tables with valid keys\n- generate dimensional/star-schema examples from SQL DDL contracts\n- save generation manifests for reproducibility and provenance\n- run an optional MCP server for assistant-driven local generation workflows\n- convert generated data to Hugging Face Datasets and generate dataset cards\n- use prebuilt enterprise domain packs\n- simulate CDC records, anomalies, SCD2 history, dimensional models, and Data Vault models\n- export domain datasets to CSV, JSON, Parquet, and Delta\n\n## Agent Skills\n\nGreat Generator is a deterministic synthetic-data engine for engineering and testing\nworkflows. Optional **Agent Skills** help AI coding agents select the right API,\ngenerate fixtures, validate results and return usable DataFrames and manifests.\nThey do not replace `generate_from_schema` or use an LLM to generate rows.\n\n| Workflow skill | What you can ask |\n|---|---|\n| `schema-test-data` | Generate checked fixtures from a schema, DDL, JSON Schema, dbt model or data dictionary |\n| `query-test-data` | Create data that exercises SQL filters, dates, groups and joins, with coverage evidence |\n| `relational-test-fixtures` | Build related tables and explicitly verify PK/FK integrity |\n| `data-pipeline-test-pack` | Create happy, boundary, opt-in invalid, CDC and SCD2 comparison cases |\n| `schema-change-regression` | Compare contracts, identify affected fixtures and plan requested regeneration |\n| `databricks-test-data` | Create Spark fixtures and safely prepare Delta/Unity Catalog test outputs |\n\nFor Databricks: \"Generate 100K rows for this StructType,\" \"Create CDC fixtures for\nmy Delta MERGE,\" or \"Create PK/FK-consistent Delta test tables.\" The skill first\nchecks API support, driver versus distributed generation, validation and write\nsafety; it does not assume a workspace or promise untested scale.\n\nStart with [installation and usage](docs/AGENT_SKILLS.md),\n[the six skills](skills/README.md), and [the Databricks guide](docs/DATABRICKS_AGENT_SKILL.md).\nThe skills are optional repository/source-distribution resources, not automatically\ninstalled into an agent by pip. [Audit and limitations](docs/AGENT_SKILLS_AUDIT.md)\ndistinguish implemented helpers, existing MCP tools and runtime-dependent checks.\n\n## AI advisor layer\n\nGreat Generator includes an optional advisor layer for design-time help with schema understanding, column tagging, and realism review. Advisors do not generate row data. They produce JSON artifacts, such as a `GenerationPlan` or `ColumnTags`, that you can inspect, edit, save, and review before generation.\n\nGeneration remains deterministic. Given the same schema, plan, seed, and arguments, the generated output stays the same. The default is `advisor=\"none\"`, which makes no model calls, reads no API keys, and works without network access.\n\n```python\nfrom great_generator import generate_from_schema, infer_generation_plan\n\nplan = infer_generation_plan(\"customer_id int, customer_name string\", advisor=\"none\")\ndf = generate_from_schema(\"customer_id int, customer_name string\", rows=100, plan=plan)\n```\n\nOnline and offline advisors are separate from generation. Anthropic, Ollama, and optional local Transformers models are supported in this layer, while OpenAI and llama.cpp are reserved as clear stubs for later implementation. See [docs/advisors.md](docs/advisors.md) and [Transformers Advisor](docs/TRANSFORMERS_ADVISOR.md) for usage, caching, prompt safety, and plan review. Advisor contribution can also be recorded in manifest metadata for auditability.\n\n## Release Highlights\n\n| Version | Release focus | What changed |\n|---|---|---|\n| 0.1.8 | Schema ingestion, optional MCP, SEO, org links, and architecture | Added JSON Schema ingestion, dbt `schema.yml` and `manifest.json` ingestion, CSV/YAML/JSON data dictionary ingestion, schema input docs, query-aware coverage examples, optional `great-generator[mcp]` support, local-file MCP tools, safety controls, tests, sitemap, robots.txt, SEO metadata, GreatDataLabs documentation links, and the architecture diagram. |\n| 0.1.7 | SQL DDL contracts and query-aware generation | Added canonical contracts, `parse_ddl(...)`, optional query-aware required values, partitioning, selectivity, relational join coverage, a runnable retail star-schema example, generation manifest guidance, determinism docs, benchmark methodology, and citation metadata. |\n| 0.1.6 | AI advisor planning layer | Added optional design-time advisors for schema understanding, column tagging, and realism review. Added editable `GenerationPlan` and `ColumnTags` JSON artifacts, cached Anthropic and Ollama advisor calls, offline NoOp defaults, manifest metadata, and deterministic `plan=` support in `generate_from_schema`. |\n| 0.1.5 | Schema-first docs and Spark database writes | Repositioned schema generation as the primary workflow. Added a schema input support matrix, Databricks and PySpark examples for Snowflake and Azure SQL, and documentation site updates. |\n| 0.1.4 | PyPI author presentation | Added a PyPI-friendly Author section with project links. |\n| 0.1.3 | PyPI metadata visibility | Updated package metadata so PyPI shows author and maintainer details more clearly. |\n| 0.1.2 | Schema realism quality | Added semantic-field based schema generation, custom rules, validation reports, and realistic schema defaults. |\n| 0.1.1 | Advanced generation APIs | Added anomaly labels, SCD2 history, recipes, CLI, dimensional models, and Data Vault models. |\n| 0.1.0 | Initial public release | Added package identity, domain packs, Pandas and Spark engines, exports, CDC, anomalies, schema generation, and relational generation. |\n\n## Useful Guides\n\n- [Schema inputs](docs/SCHEMA_INPUTS.md)\n- [JSON Schema ingestion](docs/JSON_SCHEMA.md)\n- [dbt integration](docs/DBT_INTEGRATION.md)\n- [Data dictionary ingestion](docs/DATA_DICTIONARY.md)\n- [SQL contracts and DDL](docs/CONTRACTS_AND_DDL.md)\n- [Query-aware generation](docs/QUERY_AWARE_GENERATION.md)\n- [Contract-to-Test SQL workload generation](docs/CONTRACT_TO_TEST.md)\n- [Determinism and reproducibility](docs/DETERMINISM.md)\n- [Generation manifest](docs/GENERATION_MANIFEST.md)\n- [Optional MCP server](docs/MCP_SERVER.md)\n- [Hugging Face integration](docs/HUGGINGFACE_INTEGRATION.md)\n- [Transformers advisor](docs/TRANSFORMERS_ADVISOR.md)\n- [Databricks Unity Catalog integration](docs/DATABRICKS_UNITY_CATALOG.md)\n- [UC relational generation](docs/UC_RELATIONAL_GENERATION.md)\n- [UC ingestion notebook generation](docs/UC_INGESTION_CODE_GENERATION.md)\n- [UC schema snapshots and drift detection](docs/UC_SCHEMA_SNAPSHOTS.md)\n- [Website search discovery and SEO maintenance](docs/SEO.md)\n- [Provenance and safety notes](docs/PROVENANCE.md)\n- [Benchmark methodology](docs/BENCHMARKS.md)\n- [Spark and database writes](docs/SPARK_DATABASE_WRITES.md)\n\n## Website and search discovery\n\nThe GitHub Pages site includes a sitemap and robots.txt for search discovery.\n\n- Sitemap: `https://greatdatalabs.github.io/great-generator/sitemap.xml`\n- Robots: `https://greatdatalabs.github.io/great-generator/robots.txt`\n\nSee [`docs/SEO.md`](docs/SEO.md) for the release checklist and sitemap maintenance steps.\n\n## Installation\n\n```bash\npip install great-generator\n```\n\nOptional Spark and Delta dependencies:\n\n```bash\npip install \"great-generator[spark]\"\npip install \"great-generator[delta]\"\npip install \"great-generator[databricks]\"\n```\n\nOptional advisor dependencies:\n\n```bash\npip install \"great-generator[ai]\"\npip install \"great-generator[anthropic]\"\npip install \"great-generator[ollama]\"\npip install \"great-generator[transformers]\"\n```\n\nOptional Hugging Face ecosystem helpers:\n\n```bash\npip install \"great-generator[hf]\"\npip install \"great-generator[hf-full]\"\n```\n\nOptional schema-ingestion dependencies for dbt `schema.yml` and YAML data dictionaries:\n\n```bash\npip install \"great-generator[dbt]\"\npip install \"great-generator[schema-ingest]\"\n```\n\nOptional MCP dependency:\n\n```bash\npip install \"great-generator[mcp]\"\npip install \"great-generator[cloud]\"\n```\n\nInstall with a hyphen and import with an underscore:\n\n```python\nimport great_generator\n```\n\nThe base package supports Python 3.9 and later and installs Pandas, NumPy, PyArrow, Faker, and SQLGlot for SQL DDL parsing. PySpark and Delta Lake remain optional.\n\n## Optional MCP server\n\nGreat Generator includes an optional MCP server so AI assistants can call selected tools such as schema-based generation, relational generation, SQL DDL parsing, query coverage validation, and local file export.\n\nMCP support is optional. The core package does not require MCP dependencies.\n\n```bash\npip install \"great-generator[mcp]\"\npip install \"great-generator[cloud]\"\n```\n\nStart the server:\n\n```bash\ngreat-generator-mcp\n```\n\nor:\n\n```bash\npython -m great_generator.mcp.server\n```\n\nThe MCP server is a wrapper over existing public APIs. It does not introduce a new generation engine. It writes generated datasets to local files and returns row counts, file paths, schema summaries, previews, warnings, and manifest information. It does not send data to production systems and does not overwrite files unless `overwrite=True`.\n\n```mermaid\nflowchart LR\n A[MCP Client Claude Desktop, Cursor, VS Code, other clients] --> B[Great Generator MCP Server]\n B --> C[Safety Layer path checks, row limits, overwrite protection]\n C --> D[Tool Registry]\n D --> E[parse_ddl]\n D --> F[generate_from_schema]\n D --> G[generate_relational]\n D --> H[validate_query_coverage]\n D --> I[export_dataset]\n E --> J[Great Generator Core APIs]\n F --> J\n G --> J\n H --> J\n I --> J\n J --> K[Local Output Files CSV, JSONL, Parquet]\n J --> L[Manifest and Preview]\n```\n\nSee [docs/MCP_SERVER.md](docs/MCP_SERVER.md) for client configuration, safety limits, output behavior, example prompts, and troubleshooting.\n\n## Quick Start: Generate Data from Schema\n\n```python\nfrom great_generator import generate_from_schema\n\nschema = {\n \"customer_id\": \"string\",\n \"customer_name\": \"string\",\n \"age\": \"int\",\n \"email\": \"string\",\n \"address\": \"string\",\n \"city\": \"string\",\n \"state\": \"string\",\n \"created_at\": \"datetime\",\n \"account_status\": \"string\",\n}\n\ndf = generate_from_schema(schema=schema, rows=1000)\n```\n\nThe default `realism=\"realistic\"` mode produces name-like, email-like, address-like, date-aware, and business-oriented values when field semantics are recognized.\n\nExample shape:\n\n```text\ncustomer_id customer_name age email city state account_status\nCUST000001 Ava Johnson 34 ava.johnson@example.com Austin Texas Active\nCUST000002 Liam Patel 42 liam.patel@example.com Seattle Washington Pending\n```\n\nExact values vary. Pass an optional `seed` only when your test or experiment needs repeatable output.\n\n## Schema input options\n\nGreat Generator can generate synthetic data from several schema sources, including Python mappings, compact DDL strings, SQL `CREATE TABLE` DDL, Pandas schemas, PySpark schemas, JSON Schema, dbt metadata, and data dictionaries.\n\nSee [`docs/SCHEMA_INPUTS.md`](docs/SCHEMA_INPUTS.md) for the supported input matrix.\n\n### JSON Schema\n\n```python\nfrom great_generator import generate_from_json_schema\n\njson_schema = {\n \"type\": \"object\",\n \"properties\": {\n \"customer_id\": {\"type\": \"integer\"},\n \"email\": {\"type\": \"string\", \"format\": \"email\"},\n \"status\": {\"type\": \"string\", \"enum\": [\"ACTIVE\", \"INACTIVE\", \"PENDING\"]},\n },\n}\n\ndf = generate_from_json_schema(json_schema, rows=1000)\n```\n\n### dbt schema.yml or manifest.json\n\n```python\nfrom great_generator import generate_from_dbt_schema, generate_from_dbt_manifest\n\ndf = generate_from_dbt_schema(\"models/schema.yml\", model_name=\"customers\", rows=1000)\n\nfrom_manifest = generate_from_dbt_manifest(\n \"target/manifest.json\",\n model_name=\"customers\",\n rows=1000,\n)\n```\n\n### Data dictionary CSV/YAML/JSON\n\n```python\nfrom great_generator import generate_from_data_dictionary, load_data_dictionary\n\nschema = load_data_dictionary(\"data_dictionary.csv\")\ndf = generate_from_data_dictionary(\"data_dictionary.csv\", rows=1000)\n```\n\n```mermaid\nflowchart LR\n A[Schema Sources] --> B[Schema Normalization]\n A1[Python dict] --> A\n A2[SQL DDL] --> A\n A3[JSON Schema] --> A\n A4[dbt schema.yml] --> A\n A5[dbt manifest.json] --> A\n A6[Data dictionary] --> A\n\n B --> C[Generation Contract]\n C --> D[Existing Generation Engine]\n D --> E[Synthetic Data]\n\n F[Optional Query-Aware Inputs] --> D\n F1[required_values] --> F\n F2[partition_by] --> F\n F3[target_selectivity] --> F\n\n E --> G[Validation and Coverage Reports]\n E --> H[Exports]\n```\n\nAll schema inputs are normalized into the existing generation path. No second generation engine is introduced.\n\n## Databricks Unity Catalog metadata-driven generation\n\nIf your schema and relationships already exist in Unity Catalog, Great Generator can inspect the metadata you are permitted to see and normalize it into the same generation contracts used elsewhere in the library. Metadata discovery does **not** read source table records.\n\n```python\nfrom great_generator import (\n generate_relational_from_unity_catalog,\n inspect_unity_catalog_table,\n)\n\nsnapshot = inspect_unity_catalog_table(\n \"retail.sales.fact_orders\",\n include_related=True,\n related_direction=\"parents\",\n spark=spark,\n)\n\ndatasets, report = generate_relational_from_unity_catalog(\n \"retail.sales.fact_orders\",\n include_related=True,\n rows={\n \"dim_customer\": 10_000,\n \"dim_product\": 1_000,\n \"fact_orders\": 100_000,\n },\n output=\"spark\",\n spark=spark,\n return_report=True,\n)\n```\n\nThe integration supports bounded parent/child discovery, declared and explicit relationships, clearly labeled conservative inference, simple and composite key validation, Pandas or Spark output, metadata snapshots, schema drift reports, portable synthetic CDC events, and a review-first Databricks notebook builder. Generated notebooks keep writes disabled and never overwrite existing tables by default.\n\nStart with the [Unity Catalog guide](docs/DATABRICKS_UNITY_CATALOG.md) and the [offline-first notebook series](examples/databricks/unity_catalog/README.md). The Databricks SDK is optional; notebook users can pass the active `spark` session.\n\n## Next: Generate Related Tables from Your Schemas\n\nUse `generate_relational` when your test environment needs several tables with valid primary-key and foreign-key relationships.\n\n```python\nfrom great_generator import generate_relational\n\ndata = generate_relational(\n tables={\n \"customers\": {\n \"schema\": \"customer_id int primary key, customer_name string, email string\",\n \"rows\": 1000,\n },\n \"orders\": {\n \"schema\": \"order_id int primary key, customer_id int references customers.customer_id, order_amount double, order_date date\",\n \"rows\": 5000,\n },\n },\n engine=\"pandas\",\n)\n\ncustomers_df = data[\"customers\"]\norders_df = data[\"orders\"]\n```\n\nThe result is a dictionary of named DataFrames. Each order references a generated customer, and users remain free to write each DataFrame to CSV, Parquet, Delta, Snowflake, Azure SQL, or another destination.\n\n```python\ncustomers_df.to_parquet(\"customers.parquet\", index=False)\norders_df.to_parquet(\"orders.parquet\", index=False)\n```\n\nSelect `engine=\"spark\"` in a Spark notebook to receive Spark DataFrames instead of Pandas DataFrames.\n\n## Query-aware generation\n\nGreat Generator can create synthetic data that contains the values, partition dates, and join paths needed by your SQL queries. This helps teams test SQL logic, partition pruning, joins, aggregations, and environment-specific performance behavior without using production data.\n\nAll query-aware options are optional. Existing generation behavior is unchanged unless you provide `required_values`, `partition_by`, `target_selectivity`, `ensure_join_coverage`, or `query_profile`.\n\n```python\ndf = generate_from_schema(\n schema=schema,\n rows=100_000,\n required_values={\n \"region\": [\"SOUTH\"],\n \"product_type\": [\"CHECKING\", \"SAVINGS\"],\n },\n partition_by={\n \"column\": \"business_date\",\n \"values\": [\"2026-01-01\", \"2026-01-02\", \"2026-01-03\"],\n \"distribution\": \"balanced\",\n },\n target_selectivity={\n \"region\": {\"SOUTH\": 0.25},\n },\n)\n```\n\nFor relational datasets, use table-qualified columns and `ensure_join_coverage=True` when fact rows must join to required dimension values.\n\nSee [Query-Aware Generation](docs/QUERY_AWARE_GENERATION.md).\n\n## Contract-to-Test synthetic data generation\n\nWhen required values are not enough, `compile_test_dataset(...)` analyzes a documented SQL subset\nand creates bounded witness rows that exercise predicate truth states, join paths, NULL behavior,\nand thresholds. It returns normal Pandas DataFrames plus validation, coverage, expected bounded\noutcomes, and reproducibility artifacts.\n\n```python\nfrom great_generator.testing import compile_test_dataset\n\ntables = {\n \"customers\": \"customer_id int primary key, region string not null\",\n \"orders\": (\n \"order_id int primary key, \"\n \"customer_id int references customers.customer_id, \"\n \"status string not null, order_date date not null\"\n ),\n}\n\nquery = \"\"\"\nSELECT *\nFROM orders o\nJOIN customers c ON o.customer_id = c.customer_id\nWHERE c.region = 'EAST'\n AND o.status = 'COMPLETED'\n AND o.order_date >= DATE '2026-01-01'\n\"\"\"\n\nresult = compile_test_dataset(\n schema=tables,\n queries=[query],\n rows={\"customers\": 30, \"orders\": 60},\n coverage=[\"predicates\", \"joins\", \"boundaries\"],\n seed=42,\n)\n\ndatasets = result.datasets\nassert result.validate()[\"passed\"]\nprint(result.coverage_report())\n```\n\nThe compiler parses SQL but does not execute it. Phase 1 supports Pandas and a bounded SELECT\nsubset; OR/NOT combined guarantees, Spark-native witnesses, generic composite/cyclic generation,\nand full-query equivalence remain later phases. Coverage percentages always state their supported\ndenominator.\n\nSee [Contract-to-Test](docs/CONTRACT_TO_TEST.md), the\n[feature-gap analysis](docs/engineering/FEATURE_GAP_ANALYSIS.md), and the\n[executed local mutation fixture](benchmarks/reports/contract_to_test_missing_filter_local.json).\n\n\n## Hugging Face integration\n\nGreat Generator can optionally integrate with the Hugging Face ecosystem. You can convert generated Pandas outputs to Hugging Face Datasets, convert related tables into `DatasetDict` objects, generate dataset cards for synthetic datasets, and use a local Transformers model as a design-time advisor.\n\n```bash\npip install \"great-generator[hf]\"\npip install \"great-generator[transformers]\"\n```\n\nConvert generated data locally:\n\n```python\nfrom great_generator import generate_from_schema, to_hf_dataset\n\ndf = generate_from_schema(\"customer_id int, email string\", rows=1000, seed=42)\ndataset = to_hf_dataset(df)\n```\n\nUse a local or cached Transformers model as a planning advisor:\n\n```python\nfrom great_generator import generate_from_schema, infer_generation_plan\n\nschema = \"customer_id int, email string\"\nplan = infer_generation_plan(\n schema,\n advisor=\"transformers:google/flan-t5-small\",\n)\n\ndf = generate_from_schema(schema, rows=1000, plan=plan, seed=42)\n```\n\nThe Transformers advisor runs at design time. It produces plans, tags, or reports. It does not generate row data. Hugging Face dependencies are optional, conversions are local, and Great Generator does not upload anything to the Hugging Face Hub automatically.\n\nSee [Hugging Face Integration](docs/HUGGINGFACE_INTEGRATION.md), [Transformers Advisor](docs/TRANSFORMERS_ADVISOR.md), and [`examples/huggingface`](examples/huggingface/README.md).\n\n\n## Platform examples\n\nGreat Generator includes examples for common data engineering environments:\n\n- Pandas and local development\n- Databricks and Delta Lake\n- Microsoft Fabric Lakehouse\n- Snowflake stage/COPY workflows\n- Cloud storage paths such as S3, ADLS Gen2, and GCS\n\nThese examples show how to generate synthetic data from schemas, JSON Schema, dbt metadata, data dictionaries, relationships, CDC patterns, anomalies, and query-aware profiles, then write the generated DataFrames using the user's own runtime and storage configuration.\n\nStart here:\n\n| Platform | Folder |\n|---|---|\n| Pandas/local notebooks | [`examples/pandas`](examples/pandas/README.md) |\n| Databricks notebooks | [`examples/databricks`](examples/databricks/README.md) |\n| Unity Catalog metadata workflows | [`examples/databricks/unity_catalog`](examples/databricks/unity_catalog/README.md) |\n| Microsoft Fabric notebooks | [`examples/fabric`](examples/fabric/README.md) |\n| Snowflake examples | [`examples/snowflake`](examples/snowflake/README.md) |\n| Cloud storage examples | [`examples/cloud_storage`](examples/cloud_storage/README.md) |\n\nSee [Platform Examples](docs/PLATFORM_EXAMPLES.md).\n\n## Optional cloud export helpers\n\nGreat Generator can write generated datasets to local files and, with optional cloud dependencies, to S3, ADLS Gen2, and Google Cloud Storage paths.\n\n```bash\npip install \"great-generator[cloud]\"\n```\n\n```python\nfrom great_generator import export_dataset, generate_from_schema\n\ndf = generate_from_schema(\"customer_id int, email string\", rows=1000)\nexport_dataset(df, \"output/customers\", format=\"parquet\")\n```\n\n`export_dataset` rejects existing outputs by default. Pass `overwrite=True` or `mode=\"overwrite\"` only when replacing files is intentional. Great Generator does not configure credentials or manage cloud permissions. Configure credentials using your platform's standard method.\n\nSee [Cloud Exports](docs/CLOUD_EXPORTS.md).\n\n## Synthetic benchmark harness\n\nGreat Generator includes benchmark examples that generate repeatable synthetic datasets and SQL query templates for Databricks, Microsoft Fabric, Snowflake, and Spark-style environments.\n\nThese examples are not universal performance claims. Results depend on warehouse size, cluster configuration, storage layout, file format, statistics, clustering, caching, concurrency, and query engine settings.\n\nThe first implemented harness dataset is a retail star schema:\n\n```bash\npython benchmarks/datasets/retail_star_schema/generate_dataset.py --output output/retail_star_schema --format parquet --overwrite\n```\n\nSee [Benchmark Harness](docs/BENCHMARK_HARNESS.md) and [`benchmarks/`](benchmarks/README.md).\n\n## Flagship Example: Retail Star Schema from SQL DDL\n\nIf you want a demo that feels closer to an analytics engineering or lakehouse workload, start with the retail star-schema example:\n\n```bash\npython examples/06-retail-star-schema/generate.py\npython examples/06-retail-star-schema/validate.py\n```\n\nIt parses a SQL DDL contract, generates related dimension and fact tables, applies deterministic retail behavior, validates primary keys and foreign keys, writes table-per-folder outputs, and creates a generation manifest.\n\n```text\ndim_customer\ndim_product\ndim_store\ndim_date\nfact_sales\n```\n\nSee [`examples/06-retail-star-schema`](examples/06-retail-star-schema/README.md).\n\n## Supported Schema Input Types\n\nThe table below reflects the current implementation, not the long-term roadmap.\n\n| Schema Input Type | Example | Best For | Status |\n|---|---|---|---|\n| Plain Python mapping | `{\"name\": \"string\", \"age\": \"int\"}` | Fast schema-based generation | **Supported** |\n| Rich mapping with inline metadata | `{\"age\": {\"type\": \"int\", \"min\": 18}}` | Embedded business rules | **Partially supported** through separate `custom_rules`; inline metadata is planned |\n| Pandas dtype mapping | `df.dtypes.to_dict()` | Pandas and notebook workflows | **Supported** |\n| Pandas DataFrame schema | empty or populated `DataFrame` | Preserve Pandas column dtypes | **Supported** |\n| Compact DDL string | `\"id int, name string\"` | SQL-like and Spark-style definitions | **Supported** |\n| Full SQL `CREATE TABLE` DDL | `CREATE TABLE ...` | Database, warehouse, lakehouse, and contract-first teams | **Supported** for documented ANSI, Spark, and Databricks subset |\n| PySpark `StructType` | `StructType([...])` | Databricks, Fabric, Synapse, EMR, Spark | **Supported** for common scalar types; nested complex generation is limited |\n| PySpark DataFrame | empty or existing Spark DataFrame | Infer schema and Spark session | **Supported** |\n| `TableSchema` | library schema object | Typed library extensions | **Supported** |\n| `DomainSchema` | library domain metadata | Multi-table schema generation | **Supported** |\n| JSON Schema | `{\"type\": \"object\", \"properties\": ...}` | APIs and data contracts | **Supported** through `generate_from_json_schema` for the documented v1 subset |\n| dbt `schema.yml` | `models/schema.yml` | Analytics engineering and dbt contracts | **Supported** through `generate_from_dbt_schema` |\n| dbt `manifest.json` | `target/manifest.json` | Compiled dbt project metadata | **Supported** through `generate_from_dbt_manifest` |\n| Data dictionary CSV/YAML/JSON | `data_dictionary.csv` | Enterprise schema documentation | **Supported** through `generate_from_data_dictionary` |\n| YAML dataset recipe | `recipe.yml` | Reusable generation jobs | **Supported** through `generate_from_recipe` |\n| Column-name list | `[\"name\", \"age\", \"email\"]` | Very fast prototypes | **Planned** |\n| SQLAlchemy model | ORM class | Backend and database teams | **Planned** |\n| Pydantic model | `BaseModel` class | API contract workflows | **Planned** |\n| Dataclass | typed Python dataclass | Typed Python workflows | **Planned** |\n\nJSON, YAML, and TOML dataset recipes are separate from schema-source ingestion. Use `generate_from_recipe` for complete generation jobs and the schema-source functions when you want to generate from a schema contract.\n\n## Supported Schema Examples\n\n### 1. Plain Python Dictionary\n\n```python\nfrom great_generator import generate_from_schema\n\nschema = {\n \"employee_id\": \"string\",\n \"emp_name\": \"string\",\n \"email\": \"string\",\n \"employee_age\": \"int\",\n \"salary\": \"float\",\n \"hire_date\": \"date\",\n \"employment_status\": \"string\",\n}\n\nemployees = generate_from_schema(schema, rows=500, domain=\"hr\")\n```\n\n### 2. Compact DDL String\n\nCompact column definitions are supported when you want a fast one-table schema without table-level SQL metadata. Use full `CREATE TABLE` DDL when you want a canonical contract with table names, keys, constraints, and parser diagnostics.\n\n```python\nfrom great_generator import generate_from_schema\n\ncustomers = generate_from_schema(\n \"customer_id string, customer_name string, age int, email string, balance decimal(12,2), created_at timestamp\",\n rows=1000,\n)\n```\n\nSpark-style `struct<...>` text is also accepted:\n\n```python\ndf = generate_from_schema(\n \"struct\",\n rows=1000,\n)\n```\n\n### 3. Full SQL `CREATE TABLE` DDL\n\nUse `parse_ddl` when your source of truth is database, warehouse, lakehouse, or Spark SQL DDL. It returns a canonical contract that preserves table names, column order, normalized types, primary keys, foreign keys, unique constraints, checks, defaults, comments, and selected Spark/Databricks storage metadata.\n\n```python\nfrom great_generator import generate_from_schema, parse_ddl\n\nddl = \"\"\"\nCREATE TABLE sales.customers (\n customer_id BIGINT PRIMARY KEY,\n customer_name STRING NOT NULL,\n email VARCHAR(120) UNIQUE,\n signup_date DATE,\n created_at TIMESTAMP DEFAULT current_timestamp()\n);\n\nCREATE TABLE sales.orders (\n order_id BIGINT PRIMARY KEY,\n customer_id BIGINT NOT NULL,\n order_amount DECIMAL(12, 2),\n order_date DATE,\n CONSTRAINT fk_orders_customers\n FOREIGN KEY (customer_id) REFERENCES sales.customers(customer_id)\n)\n\"\"\"\n\ncontract = parse_ddl(ddl, dialect=\"databricks\")\nprint(contract.fingerprint())\nprint(contract.tables[\"sales.orders\"].foreign_keys[0].parent_table)\n```\n\nFor one-table DDL, you can generate directly from the parsed contract:\n\n```python\ncustomer_contract = parse_ddl(\n \"\"\"\n CREATE TABLE customers (\n customer_id BIGINT PRIMARY KEY,\n customer_name STRING,\n email STRING,\n signup_date DATE\n )\n \"\"\",\n dialect=\"databricks\",\n)\n\ndf = generate_from_schema(customer_contract, rows=1000)\n```\n\nFor multiple related tables, parsing support is complete for the documented constraint metadata. Existing simple single-column relationships can generate through `generate_from_schema(contract, rows={...})`; composite-key and cyclic relational generation are parsed today and planned for a later relational milestone.\n\nSupported DDL subset today:\n\n| Construct | Status | Notes |\n|---|---|---|\n| One or more `CREATE TABLE` statements | Supported | Non-table statements are rejected |\n| Schema-qualified names | Supported | Unquoted identifiers are normalized to lowercase; quoted identifiers preserve case and spaces |\n| Scalar SQL, Spark, Databricks types | Supported | `INT`, `BIGINT`, `STRING`, `VARCHAR`, `DECIMAL`, `DOUBLE`, `BOOLEAN`, `DATE`, `TIMESTAMP`, `TIMESTAMP_NTZ`, `BINARY` |\n| Inline and table primary keys | Supported | Single and composite metadata is preserved |\n| Inline and table foreign keys | Supported | Single, composite, multiple, and self-referencing metadata is preserved |\n| Unique constraints | Supported | Inline and table-level |\n| Check constraints | Supported as metadata | Used for contract visibility, not row-level enforcement yet |\n| Defaults and comments | Supported as metadata | Preserved for inspection and planning |\n| `USING DELTA`, `PARTITIONED BY` | Supported as metadata | Useful in Databricks/Spark contracts |\n| Identity/generated columns, CTAS, unsupported types | Explicit diagnostics | Strict mode fails; permissive mode only warns when safe |\n\n```python\nfrom great_generator.contracts import ContractParseError\n\ntry:\n contract = parse_ddl(ddl, dialect=\"databricks\", strict=True)\nexcept ContractParseError as exc:\n for diagnostic in exc.diagnostics:\n print(diagnostic.construct, diagnostic.message)\n```\n\n### 4. Pandas dtype Mapping\n\n```python\nimport pandas as pd\n\nfrom great_generator import generate_from_schema\n\nsample_df = pd.DataFrame(\n {\n \"customer_id\": pd.Series(dtype=\"string\"),\n \"customer_name\": pd.Series(dtype=\"string\"),\n \"age\": pd.Series(dtype=\"int64\"),\n \"balance\": pd.Series(dtype=\"float64\"),\n \"created_at\": pd.Series(dtype=\"datetime64[ns]\"),\n }\n)\n\ndf = generate_from_schema(sample_df.dtypes.to_dict(), rows=1000)\n```\n\n### 5. Pandas DataFrame Schema\n\nPass the DataFrame itself when you want Great Generator to infer and cast back to its dtypes:\n\n```python\ndf = generate_from_schema(sample_df, rows=1000)\n```\n\nThe input rows are not copied. The DataFrame is used as a schema source.\n\n### 6. PySpark StructType\n\n```python\nfrom pyspark.sql.types import (\n DoubleType,\n IntegerType,\n StringType,\n StructField,\n StructType,\n TimestampType,\n)\n\nfrom great_generator import generate_from_schema\n\nschema = StructType(\n [\n StructField(\"customer_id\", StringType(), False),\n StructField(\"customer_name\", StringType(), True),\n StructField(\"age\", IntegerType(), True),\n StructField(\"email\", StringType(), True),\n StructField(\"balance\", DoubleType(), True),\n StructField(\"created_at\", TimestampType(), True),\n ]\n)\n\nspark_df = generate_from_schema(schema=schema, rows=1000, engine=\"spark\")\n```\n\nIn a notebook or cluster with an active Spark session, `engine=\"spark\"` resolves that session automatically. You can also pass `spark=spark` explicitly when no active session can be discovered.\n\nCurrent limitation: single-table Spark schema generation creates values locally and then creates a Spark DataFrame. Use environment-appropriate row counts. Native distributed generation for this API is planned; the built-in Spark domain engine already uses Spark-native generation paths.\n\n### 7. PySpark DataFrame Schema\n\n```python\nempty_spark_df = spark.createDataFrame([], schema)\n\nspark_df = generate_from_schema(empty_spark_df, rows=1000)\n```\n\nThe input DataFrame supplies both the schema and Spark session. The returned value is a Spark DataFrame and supports normal Spark writers.\n\n### 8. Library TableSchema\n\n```python\nfrom great_generator import generate_from_schema\nfrom great_generator.schemas.models import ColumnSpec, TableSchema\n\nschema = TableSchema(\n name=\"customers\",\n columns=(\n ColumnSpec(\"customer_id\", \"string\", nullable=False),\n ColumnSpec(\"customer_name\", \"string\"),\n ColumnSpec(\"email\", \"string\"),\n ColumnSpec(\"age\", \"int\"),\n ),\n primary_key=\"customer_id\",\n)\n\ndf = generate_from_schema(schema, rows=1000)\n```\n\n## Rich Business Rules with `custom_rules`\n\nInline rich schema metadata is planned. Today, keep the type mapping simple and pass business rules separately:\n\n```python\nfrom great_generator import generate_from_schema\n\nschema = {\n \"customer_id\": \"string\",\n \"customer_name\": \"string\",\n \"age\": \"int\",\n \"email\": \"string\",\n \"balance\": \"float\",\n \"account_status\": \"string\",\n \"created_at\": \"datetime\",\n}\n\ncustom_rules = {\n \"customer_id\": {\"prefix\": \"CUST\"},\n \"customer_name\": {\"type\": \"full_name\"},\n \"age\": {\"min\": 18, \"max\": 85},\n \"balance\": {\"min\": 0, \"max\": 100000},\n \"account_status\": {\n \"weighted_values\": {\n \"Active\": 0.70,\n \"Inactive\": 0.15,\n \"Pending\": 0.10,\n \"Closed\": 0.05,\n }\n },\n \"created_at\": {\"start\": \"2023-01-01\", \"end\": \"2024-12-31\"},\n}\n\ndf = generate_from_schema(\n schema=schema,\n rows=5000,\n custom_rules=custom_rules,\n)\n```\n\nCurrently supported rule keys include:\n\n| Rule | Purpose |\n|---|---|\n| `type` | Override inferred semantic type, such as `full_name` |\n| `min`, `max` | Numeric or age bounds |\n| `values` | Allowed categorical values |\n| `weighted_values` | Weighted categories as a mapping or value-weight pairs |\n| `prefix` | Prefix generated ID-like fields |\n| `pattern` | Format strings using `{index}` |\n| `start`, `end` | Date generation window for date-like fields |\n| `null_rate` | Opt-in null rate for non-ID fields |\n| `unique` | Validation expectation; ID-like fields are generated uniquely by default |\n\n## Realistic Mode\n\n`realism=\"realistic\"` is the default for `generate_from_schema`.\n\n| Column Name | Data Type | Typical Behavior |\n|---|---|---|\n| `customer_name`, `cust_name` | string | realistic full name |\n| `emp_name`, `employee_name` | string | realistic employee name |\n| `age`, `employee_age` | int | age-appropriate range |\n| `email`, `email_id` | string | email-like value |\n| `phone`, `mobile_no` | string | phone-like value |\n| `address`, `city`, `state` | string | address-oriented value |\n| `customer_id` | string | unique prefixed identifier |\n| `amount`, `salary`, `balance` | numeric | bounded business-oriented amount |\n| `created_at` | date or timestamp | historical value by default |\n| `updated_at` | date or timestamp | same as or after `created_at` |\n| `date_of_birth`, `dob` | date | non-future birth date |\n| `status`, `order_status` | string | recognizable status category |\n\nRealistic mode is designed to avoid obvious placeholder behavior such as `customer_name_1`, ages outside expected human ranges, future historical dates, or `updated_at` before `created_at`.\n\nUse placeholder mode when simple deterministic values are more useful than semantic realism:\n\n```python\ndf = generate_from_schema(schema, rows=20, realism=\"placeholder\")\n```\n\n`realism=\"basic\"` and `realism=\"simple\"` are aliases for placeholder mode. `realism=\"clean\"` is an alias for realistic mode.\n\n## Data Quality and Edge Cases\n\nSchema-generated data aims to be:\n\n- fake and non-production\n- schema-aligned and type-correct\n- semantically meaningful where fields are recognized\n- logically consistent for supported cross-field rules\n- easy to validate and write downstream\n\nSupported clean-data behaviors include:\n\n- name and email consistency when first and last name fields are present\n- realistic age ranges\n- age and date-of-birth alignment\n- historical dates for fields that should not be in the future\n- `updated_at >= created_at`\n- `end_date >= start_date`\n- `delivery_date >= order_date`\n- status-aware nulls for unpaid, undelivered, active-employment, and open-account states\n- unique non-null ID-like fields\n- positive quantities\n- total calculations from quantity, price, discount, and tax where recognized\n\n### Explain the Generation Plan\n\nInspect semantic inference before generating data:\n\n```python\nfrom great_generator import explain_generation_plan\n\nplan = explain_generation_plan(\n {\n \"cust_nm\": \"string\",\n \"email_addr\": \"string\",\n \"txn_amt\": \"double\",\n \"created_ts\": \"timestamp\",\n }\n)\n\nfor field in plan[\"fields\"]:\n print(field[\"column\"], field[\"semantic_type\"], field[\"confidence\"])\n```\n\n### Validate Generated Data\n\n```python\nfrom great_generator import generate_from_schema, validate_generated_data\n\ndf = generate_from_schema(schema, rows=1000, custom_rules=custom_rules)\nreport = validate_generated_data(df, schema=schema, rules=custom_rules)\n\nassert report[\"passed\"], report[\"errors\"]\n```\n\nOr return data and a report together:\n\n```python\ndf, report = generate_from_schema(\n schema,\n rows=1000,\n validate=True,\n return_report=True,\n)\n```\n\nValidation is local for Pandas results. Spark results currently return a note rather than collecting the distributed DataFrame for local validation.\n\n## Writing Generated Data to Different Targets\n\nGreat Generator returns DataFrames so you can use the writer already trusted by your application, notebook, database driver, or Spark platform.\n\n### Write Pandas Data to CSV, JSON, or Parquet\n\n```python\ndf.to_csv(\"customers.csv\", index=False)\ndf.to_json(\"customers.json\", orient=\"records\", lines=True)\ndf.to_parquet(\"customers.parquet\", index=False)\n```\n\n### Write a Spark DataFrame to Parquet or Delta Lake\n\n```python\nspark_df.write.mode(\"overwrite\").parquet(\"/data/synthetic/customers\")\n\nspark_df.write.format(\"delta\").mode(\"overwrite\").save(\"/mnt/delta/customers\")\n```\n\nDelta support depends on a Delta-enabled Spark runtime or the `delta-spark` extra.\n\n### Write to a Databricks Table\n\n```python\nspark_df.write.format(\"delta\").mode(\"overwrite\").saveAsTable(\n \"dev.synthetic_customers\"\n)\n```\n\nTypical Databricks paths include `dbfs:/...` and `/Volumes////...`, depending on workspace configuration.\n\n### Write to a Microsoft Fabric Lakehouse\n\n```python\nspark_df.write.format(\"delta\").mode(\"overwrite\").save(\n \"Tables/synthetic_customers\"\n)\n```\n\nUse the path conventions and permissions configured for your Fabric workspace and lakehouse.\n\n### Write PySpark or Databricks Data to Snowflake\n\nFor Spark workloads, use the Snowflake Spark Connector rather than collecting data into Pandas:\n\n```python\ndef secret(key: str) -> str:\n return dbutils.secrets.get(scope=\"great-generator\", key=key)\n\n\nsnowflake_options = {\n \"sfURL\": secret(\"snowflake-url\"),\n \"sfUser\": secret(\"snowflake-user\"),\n \"sfPassword\": secret(\"snowflake-password\"),\n \"sfDatabase\": secret(\"snowflake-database\"),\n \"sfSchema\": secret(\"snowflake-schema\"),\n \"sfWarehouse\": secret(\"snowflake-warehouse\"),\n \"sfRole\": secret(\"snowflake-role\"),\n}\n\n(\n spark_df.write.format(\"net.snowflake.spark.snowflake\")\n .options(**snowflake_options)\n .option(\"dbtable\", \"SYNTHETIC_CUSTOMERS\")\n .mode(\"overwrite\")\n .save()\n)\n```\n\nInstall a Snowflake Spark Connector version compatible with the cluster's Spark and Scala versions when it is not bundled by the runtime.\n\nFor local Pandas workflows, SQLAlchemy remains an option:\n\n```python\nimport os\nfrom sqlalchemy import create_engine\n\nengine = create_engine(os.environ[\"SNOWFLAKE_SQLALCHEMY_URL\"])\ndf.to_sql(\"SYNTHETIC_CUSTOMERS\", con=engine, if_exists=\"replace\", index=False)\n```\n\nInstall and configure the appropriate Snowflake SQLAlchemy connector separately.\n\n### Write PySpark or Databricks Data to Azure SQL with JDBC\n\n```python\nserver = dbutils.secrets.get(scope=\"great-generator\", key=\"azure-sql-server\")\ndatabase = dbutils.secrets.get(scope=\"great-generator\", key=\"azure-sql-database\")\njdbc_url = (\n f\"jdbc:sqlserver://{server}:1433;\"\n f\"databaseName={database};\"\n \"encrypt=true;\"\n \"trustServerCertificate=false;\"\n \"hostNameInCertificate=*.database.windows.net;\"\n \"loginTimeout=30;\"\n)\n\n(\n spark_df.coalesce(4)\n .write.format(\"jdbc\")\n .mode(\"overwrite\")\n .option(\"url\", jdbc_url)\n .option(\"dbtable\", \"dbo.synthetic_customers\")\n .option(\"user\", dbutils.secrets.get(scope=\"great-generator\", key=\"azure-sql-user\"))\n .option(\"password\", dbutils.secrets.get(scope=\"great-generator\", key=\"azure-sql-password\"))\n .option(\"driver\", \"com.microsoft.sqlserver.jdbc.SQLServerDriver\")\n .option(\"batchsize\", \"1000\")\n .save()\n)\n```\n\nThe Microsoft SQL Server JDBC driver must be available to the Spark runtime. Limit partitions so the cluster does not overwhelm Azure SQL with concurrent connections.\n\nFor local Pandas workflows, SQLAlchemy remains an option:\n\n```python\nimport os\nfrom sqlalchemy import create_engine\n\nengine = create_engine(os.environ[\"SQLSERVER_SQLALCHEMY_URL\"])\ndf.to_sql(\"synthetic_customers\", con=engine, if_exists=\"replace\", index=False)\n```\n\nSee [Spark database writes](docs/SPARK_DATABASE_WRITES.md) for connector setup, secrets, authentication alternatives, and production notes.\n\n### Write to PostgreSQL\n\n```python\nimport os\nfrom sqlalchemy import create_engine\n\nengine = create_engine(os.environ[\"POSTGRESQL_SQLALCHEMY_URL\"])\ndf.to_sql(\"synthetic_customers\", con=engine, if_exists=\"replace\", index=False)\n```\n\n### Write to SQLite\n\n```python\nfrom sqlalchemy import create_engine\n\nengine = create_engine(\"sqlite:///synthetic_data.db\")\ndf.to_sql(\"synthetic_customers\", con=engine, if_exists=\"replace\", index=False)\n```\n\n### Write to Cloud Storage\n\nPandas can write cloud URLs when the matching filesystem package and authentication are configured:\n\n```python\ndf.to_parquet(\"s3://my-bucket/synthetic/customers.parquet\")\ndf.to_parquet(\"gs://my-bucket/synthetic/customers.parquet\")\ndf.to_parquet(\n \"abfss://container@account.dfs.core.windows.net/synthetic/customers.parquet\"\n)\n```\n\nSpark uses its runtime connectors and identity configuration:\n\n```python\nspark_df.write.mode(\"overwrite\").parquet(\"s3a://my-bucket/synthetic/customers\")\nspark_df.write.mode(\"overwrite\").parquet(\"gs://my-bucket/synthetic/customers\")\nspark_df.write.mode(\"overwrite\").parquet(\n \"abfss://container@account.dfs.core.windows.net/synthetic/customers\"\n)\n```\n\nGreat Generator does not configure credentials, filesystem connectors, IAM roles, managed identities, service accounts, secrets, catalogs, or external locations. Use environment variables, managed identities, workload identities, or secret managers. Do not hardcode credentials.\n\n## Real-World Data Engineering Use Cases\n\n### Lower-Environment Data Generation\n\nGenerate fake but realistic customer, account, order, claim, employee, transaction, or operational data for dev, QA, SIT, UAT, sandbox, and demo environments.\n\n### ETL and ELT Pipeline Testing\n\nTest ingestion, type handling, transformations, schema checks, data quality rules, and downstream loads without waiting for production extracts.\n\n### Lakehouse and Warehouse Testing\n\nReturn DataFrames that can be written to Delta Lake, Databricks, Microsoft Fabric, Snowflake, Synapse, BigQuery, Redshift, PostgreSQL, SQL Server, or other supported targets using their normal connectors.\n\n### Data Model Validation\n\nUse `generate_from_schema` for individual tables or `generate_relational` for related tables. Test keys, joins, null behavior, facts, dimensions, and lifecycle logic.\n\n### Dashboard and BI Testing\n\nCreate realistic datasets for Power BI, Tableau, Looker, notebooks, and internal analytics applications when production data cannot be shared.\n\n### API and Application Testing\n\nGenerate DataFrame-backed payloads for API contracts, application services, integration tests, and database fixtures.\n\n### Performance and Volume Testing\n\nGreat Generator is designed to support small to large datasets. It can generate one row to millions of rows depending on memory, compute, schema complexity, engine, and environment. For very large datasets, use chunking, test carefully, or use Spark-native domain generation. Do not treat a row-count setting as a performance guarantee.\n\n### AI and ML Experimentation\n\nCreate starter datasets for feature engineering, model prototyping, tutorials, and demonstrations when real data is unavailable. Generated data is not a substitute for representative training data or formal statistical synthesis.\n\n## `generate_from_schema` API Reference\n\nCurrent signature:\n\n```python\ngenerate_from_schema(\n schema,\n rows=100,\n seed=None,\n engine=\"auto\",\n spark=None,\n table_name=\"sample\",\n realism=\"realistic\",\n domain=None,\n custom_rules=None,\n plan=None,\n realistic=None,\n validate=False,\n return_report=False,\n required_values=None,\n partition_by=None,\n target_selectivity=None,\n query_profile=None,\n)\n```\n\n| Parameter | Description |\n|---|---|\n| `schema` | Supported schema object or definition, including a parsed `ContractSchema` from `parse_ddl(...)` |\n| `rows` | Integer row count for one table; mapping or integer for `DomainSchema` |\n| `seed` | Optional integer for reproducible generation |\n| `engine` | `\"auto\"`, `\"pandas\"`, or `\"spark\"` |\n| `spark` | Optional SparkSession when it cannot be inferred or discovered |\n| `table_name` | Logical name used for a single-table schema |\n| `realism` | `\"realistic\"` or `\"placeholder\"`, including documented aliases |\n| `domain` | Optional semantic preset such as `banking`, `retail`, `healthcare`, `insurance`, `hr`, or `education` |\n| `custom_rules` | Per-column semantic, range, category, pattern, date, prefix, and null rules |\n| `plan` | Optional `GenerationPlan` from `infer_generation_plan(...)`; generation consumes the plan deterministically |\n| `realistic` | Backward-compatible boolean override; prefer `realism` in new code |\n| `validate` | Run post-generation validation where supported |\n| `return_report` | Return `(data, report)` instead of only data |\n| `required_values` | Optional query-aware values that must appear in generated columns |\n| `partition_by` | Optional query-aware partition values or counts for a column |\n| `target_selectivity` | Optional approximate filter ratios for generated values |\n| `query_profile` | Optional reusable mapping containing query-aware options |\n\nReturn behavior:\n\n- Python mappings, compact DDL, one-table SQL DDL contracts, Pandas inputs, and `TableSchema` return a Pandas DataFrame by default.\n- `engine=\"spark\"`, an explicit SparkSession, or a PySpark DataFrame returns a Spark DataFrame.\n- A PySpark `StructType` returns Spark when an active or explicit SparkSession is available; otherwise auto mode resolves to Pandas.\n- `DomainSchema` and multi-table `ContractSchema` inputs return a dictionary of table-name to DataFrame.\n\n## Later: `generate_domain` for Prebuilt Learning and Demo Datasets\n\nUse domain packs when you want a complete ready-made dataset rather than data shaped around your own schema.\n\n```python\nfrom great_generator import generate_domain, list_domains\n\nprint(list_domains())\n\ndata = generate_domain(\"ecommerce\", scale=\"small\")\n\ncustomers = data[\"customers\"]\norders = data[\"orders\"]\norder_items = data[\"order_items\"]\n```\n\nAvailable domain packs include ecommerce, banking, healthcare, insurance, telecom, automotive, energy, manufacturing, logistics, media, public sector, hospitality, and SaaS.\n\nDomain packs include relationships and domain behaviors. They are useful for demonstrations, tutorials, SQL learning, architecture prototypes, benchmarks, and examples where the user does not already have a schema.\n\n## Choose the Right Generation API\n\n| Use Case | Recommended Function | Why |\n|---|---|---|\n| I already have a table schema | `generate_from_schema` | Uses your actual structure |\n| I need lower-environment test data | `generate_from_schema` | Aligns generated fields to the expected contract |\n| I need data for ETL or QA testing | `generate_from_schema` | Matches pipeline input columns and types |\n| I have several related custom tables | `generate_relational` | Adds primary-key and foreign-key relationships |\n| I have JSON Schema contracts | `generate_from_json_schema` | Uses API-style schema metadata |\n| I have dbt model metadata | `generate_from_dbt_schema` or `generate_from_dbt_manifest` | Fits analytics engineering workflows |\n| I have a CSV/YAML/JSON data dictionary | `generate_from_data_dictionary` | Works with enterprise schema documentation |\n| I have a Unity Catalog table | `generate_from_unity_catalog` | Uses permitted table metadata without reading source records |\n| I have related Unity Catalog tables | `generate_relational_from_unity_catalog` | Discovers declared keys and validates generated joins |\n| I need query values and partitions present | `generate_from_schema` with query-aware options | Ensures SQL filters and partitions have coverage |\n| I need data that exercises supported SQL conditions | `compile_test_dataset` | Compiles SQL predicates, joins, NULL states, and boundaries into validated witnesses |\n| I need a quick enterprise demo dataset | `generate_domain` | Prebuilt related tables are immediately available |\n| I am learning SQL or data modeling | `generate_domain` | Domain packs provide understandable examples |\n| I need data for my project's schema | `generate_from_schema` | This is the primary industry workflow |\n\nFor industry projects, start with `generate_from_schema`. For ready-made learning and demos, use `generate_domain`.\n\n## Later: Modeling, CDC, and Data Vault Capabilities\n\n| Capability | API |\n|---|---|\n| CDC records | `generate_cdc` |\n| Controlled anomalies | `generate_domain(..., anomalies=...)` |\n| SCD2 history | `generate_history` |\n| Dimensional facts and dimensions | `generate_dimensional_model` |\n| Data Vault hubs, links, and satellites | `generate_data_vault_model` |\n| JSON, TOML, and simple YAML recipes | `generate_from_recipe` |\n| CSV, JSON, Parquet, Delta table-per-folder exports | `export_data` or `generate_domain(..., output_format=...)` |\n| DataFrame-first local/cloud helper exports | `export_dataset` |\n\nSee the [documentation site](https://greatdatalabs.github.io/great-generator/), [Wiki](https://github.com/GreatDataLabs/great-generator/wiki), and [`docs/`](docs/) for focused guides.\n\n## Planned Schema Input Types\n\nThe following are roadmap items and are not accepted by the schema-source APIs today:\n\n- inline rich schema metadata directly inside plain Python mappings\n- column-name-only lists with type inference\n- SQLAlchemy models\n- Pydantic models\n- Python dataclasses\n- richer nested Spark and JSON structures\n- Avro and OpenAPI schema ingestion\n- Spark-native distributed generation for arbitrary schemas\n\nTracking these as explicit roadmap items keeps the current API trustworthy while leaving a clear path for contributors.\n\n## Limitations\n\n- Generated data is synthetic and may not reproduce every rule or distribution in a real system.\n- The library does not provide privacy guarantees or transform production data.\n- Semantic inference depends on recognizable field names and declared data types. Use `custom_rules` when intent is ambiguous.\n- Single-table Spark schema generation currently creates values locally before creating a Spark DataFrame.\n- Nested complex Spark types have limited generation support.\n- Full SQL DDL ingestion supports the documented ANSI, Spark, and Databricks subset. It does not claim complete coverage for every database dialect.\n- Unity Catalog generation supports declared composite PK/FK tuples and validates tuple-level joins. Generic DDL-driven composite generation and cyclic/self-referencing graph generation remain limited; cycles fail clearly instead of producing invalid data.\n- Unity Catalog metadata is permission-filtered and constraints are informational. Missing metadata may mean not declared or not visible.\n- Cloud storage and database access require separate connectors, credentials, permissions, and runtime configuration.\n- Domain packs are engineered simulations, not statistical models fitted to source data.\n- Contract-to-Test Phase 1 supports Pandas and a documented SQL subset. It does not claim complete SQL coverage, arbitrary query-result oracles, native Spark witness generation, or generic cyclic relationship support.\n\n## Roadmap\n\nPriorities include richer schema ingestion, nested contracts, native distributed schema generation, stronger generation manifests and quality reports, additional domain packs, streaming output, and expanded lifecycle behavior. See [`docs/OPEN_SOURCE_STRATEGY.md`](docs/OPEN_SOURCE_STRATEGY.md) and the [Wiki roadmap](https://github.com/GreatDataLabs/great-generator/wiki/Roadmap).\n\n## Contributing\n\nContributions are welcome. Start with [CONTRIBUTING.md](CONTRIBUTING.md), run the test suite, and include focused tests for user-visible behavior.\n\n```bash\npython -m pip install -e \".[dev]\"\npytest\nruff check .\nblack --check .\n```\n\n## Author\n\nCreated and maintained by Ravi Kiran Pagidi.\n\n- [PyPI](https://pypi.org/project/great-generator/)\n- [GitHub](https://github.com/GreatDataLabs/great-generator)\n- [Documentation](https://greatdatalabs.github.io/great-generator/)\n- [Wiki](https://github.com/GreatDataLabs/great-generator/wiki)\n- [Contact](mailto:ravikiran.pagidi@gmail.com)\n\n## Disclaimer\n\nGreat Generator helps teams create fake, non-production synthetic data. It does not guarantee compliance, privacy preservation, statistical equivalence, or fitness for a regulated use case. Review generated data and follow your organization's data governance, privacy, security, and compliance requirements.\n\n## License\n\n[MIT](LICENSE)\n"}
 \n