
skill
security-ai-scanner
AI-powered security scanner for source code — agentic LLM analysis with SARIF output
Set up
Skills are installed by placing their folder where your agent loads skills.
The download comes from github.com/elvezjp/security-ai-scanner itself, not from our server, so what you get is exactly what its author published.
Install instructions come from the README
README
synced Oct 25, 2026security-ai-scanner



AI-powered security scanner for source code. An LLM agent reads your repository with read-only tools, traces data flows from source to sink, and reports validated vulnerabilities as SARIF, JSON, and a human-readable Markdown report.
Shared AI connection settings
sais and cair read the same machine-owned TOML file at
$XDG_CONFIG_HOME/elvez-quality-gate/config.toml (default:
~/.config/elvez-quality-gate/config.toml). Create it outside the repositories
you scan or review:
[profiles.local]
engine = "openai"
base_url = "http://127.0.0.1:18080/v1"
model = "auto"
auth_token_file = "~/.config/elvez-quality-gate/local-token"
Create the token file privately and run chmod 600 on POSIX. The file is read
at each run, preserving all contents except one final LF or CRLF. Relative
credential paths in a profile resolve against the configuration directory.
A file readable by group/others, an invalid token, or a connection file inside
the target repository is rejected, including symlink destinations and parent
Git repositories when running from a subdirectory. No repository configuration
is discovered automatically.
sais scan /path/to/repo --profile local --json
cair review main...HEAD --profile local --json
sais mcp --profile local
Select a profile with --profile or SAIS_PROFILE / CAIR_PROFILE; override
the configuration file with SAIS_CONFIG / CAIR_CONFIG. A profile must be
selected to read the file. Field precedence is CLI > environment > profile >
existing defaults. Both tools accept their own *_ENGINE, *_BASE_URL,
*_MODEL, *_AUTH_TOKEN, and *_AUTH_TOKEN_FILE variables. Credential value
and credential file are one setting: a higher-priority value replaces the
lower-priority file, and vice versa. Supplying both forms at the same level
is an error. An explicit --auth-token "" suppresses lower-priority credentials.
--auth-token VALUE remains supported with a process-list/history warning;
prefer --auth-token-file PATH or the environment. Tokens, credential paths,
and profile documents are never included in provenance; reflected credentials
are redacted and HTTP error bodies are not printed. Redaction applies to free
text after schema and evidence validation; finding keys, severity, and category
keep their meaning even when a local token is a common word. HTTP redirects are refused.
model = "auto" works with the OpenAI-compatible engine only. It queries
GET /models and uses exactly one valid advertised model. Empty, malformed,
or multiple-model responses fail with exit code 2 (multiple-model errors list
up to 20 IDs). IXV beast mode is refused when reported by discovery. Each
response's model, when present, must equal the selected ID; a change aborts
without publishing findings. Discovery does not change token budgets.
summary.json.provenance records engine, model_requested, model, and
model_metadata (only file basename, context_length, and ixv_mode when
provided). Endpoints and arbitrary discovery fields are excluded. Full prompt
provenance and SARIF provenance remain separate work.
MCP resolves the operator's settings when the server starts and validates
connection-file locations against each scan target. Its model-controlled tool
arguments cannot choose a profile, endpoint, or credential. Restart the server
to change a profile; rotating the credential file takes effect on the next scan.
Direct Python ScanConfig / ReviewConfig calls never load profiles or tool
connection environment variables implicitly. Applications can explicitly opt
in with the package's connection.load_connection_settings(prefix="SAIS" or "CAIR", target=..., profile=...), then pass settings.as_kwargs(target) into
their config. Explicit auth_token_file also works in the Python API. Hosted
Claude authentication still uses the Claude SDK's own authentication mechanism.
Timeout/retry profile fields are not yet supported.
Features
- Agentic Analysis: The AI agent explores the repository itself — enumerating entry points, tracing untrusted input to dangerous sinks, and validating each candidate before reporting
- Read-Only by Design: The agent is restricted to Read / Glob / Grep; shell, write, and network tools are disallowed during a scan
- SARIF 2.1.0 Output: Findings integrate directly with GitHub Code Scanning and standard AppSec tooling
- CI Gate Built In:
--fail-on highexits non-zero when findings meet the threshold, so a scan can block a pipeline - Structured Findings: Results are produced against a JSON Schema (severity, confidence, CWE, evidence, recommendation) — no fragile text parsing
- Bilingual Reports: Finding descriptions and the Markdown report can be generated in English or Japanese (
--language ja) - Local LLM Support: Scan without sending code off the machine — point the built-in
openaiengine at any OpenAI-compatible server (vLLM, Ollama, LM Studio, llama.cpp), or the defaultclaudeengine at an Anthropic-compatible endpoint - Engine-Agnostic Core: The scanner core talks to a thin engine adapter; the default engine is the Claude Agent SDK, and other backends can be added without touching the core
Use Cases
- Pre-Release Audit: Run a full scan before shipping and review the Markdown report
- CI Security Gate: Fail pull-request pipelines when new high-severity findings appear
- GitHub Code Scanning: Upload
findings.sarifto surface findings in the Security tab - Security Triage Input: Feed
findings.jsoninto your own tracking or ticketing workflow
Documentation
- CHANGELOG.md - Version history
- CONTRIBUTING.md - Contribution guidelines
- SECURITY.md - Security policy and best practices
- PROVENANCE.md - Code and specification provenance
- THIRD_PARTY_NOTICES.md - Dependency licenses and service terms
- spec.md - English-primary technical specification (Japanese)
- Implementation roadmap - Suite order and the 0.3.0 conformance plan
- Local LLM E2E verification - Measured results for local models on a planted-vulnerability fixture
- Suite compatibility and Q8 evidence - Supported private three-product matrix and final-gate scenarios
Installation
Requires Python 3.11 or higher. Install the claude extra for the default
Claude engine. The Claude Agent SDK
bundles the Claude Code CLI and its use is also governed by Anthropic's
published commercial terms.
pip install 'security-ai-scanner[claude]'
# or with uv
uv add 'security-ai-scanner[claude]'
The built-in OpenAI-compatible local engine has no third-party runtime dependency. Install the base package when only that engine is needed:
pip install security-ai-scanner
sais scan ./repo --engine openai --base-url http://127.0.0.1:11434/v1 --model MODEL
After installation, the security-ai-scanner command (and its short
alias sais) is available on your PATH.
Authentication
The default engine authenticates the same way Claude Code does. Pick one:
# Option 1: sign in with your Claude account
claude login

# Option 2: use an API key
export ANTHROPIC_API_KEY=sk-ant-...
Usage
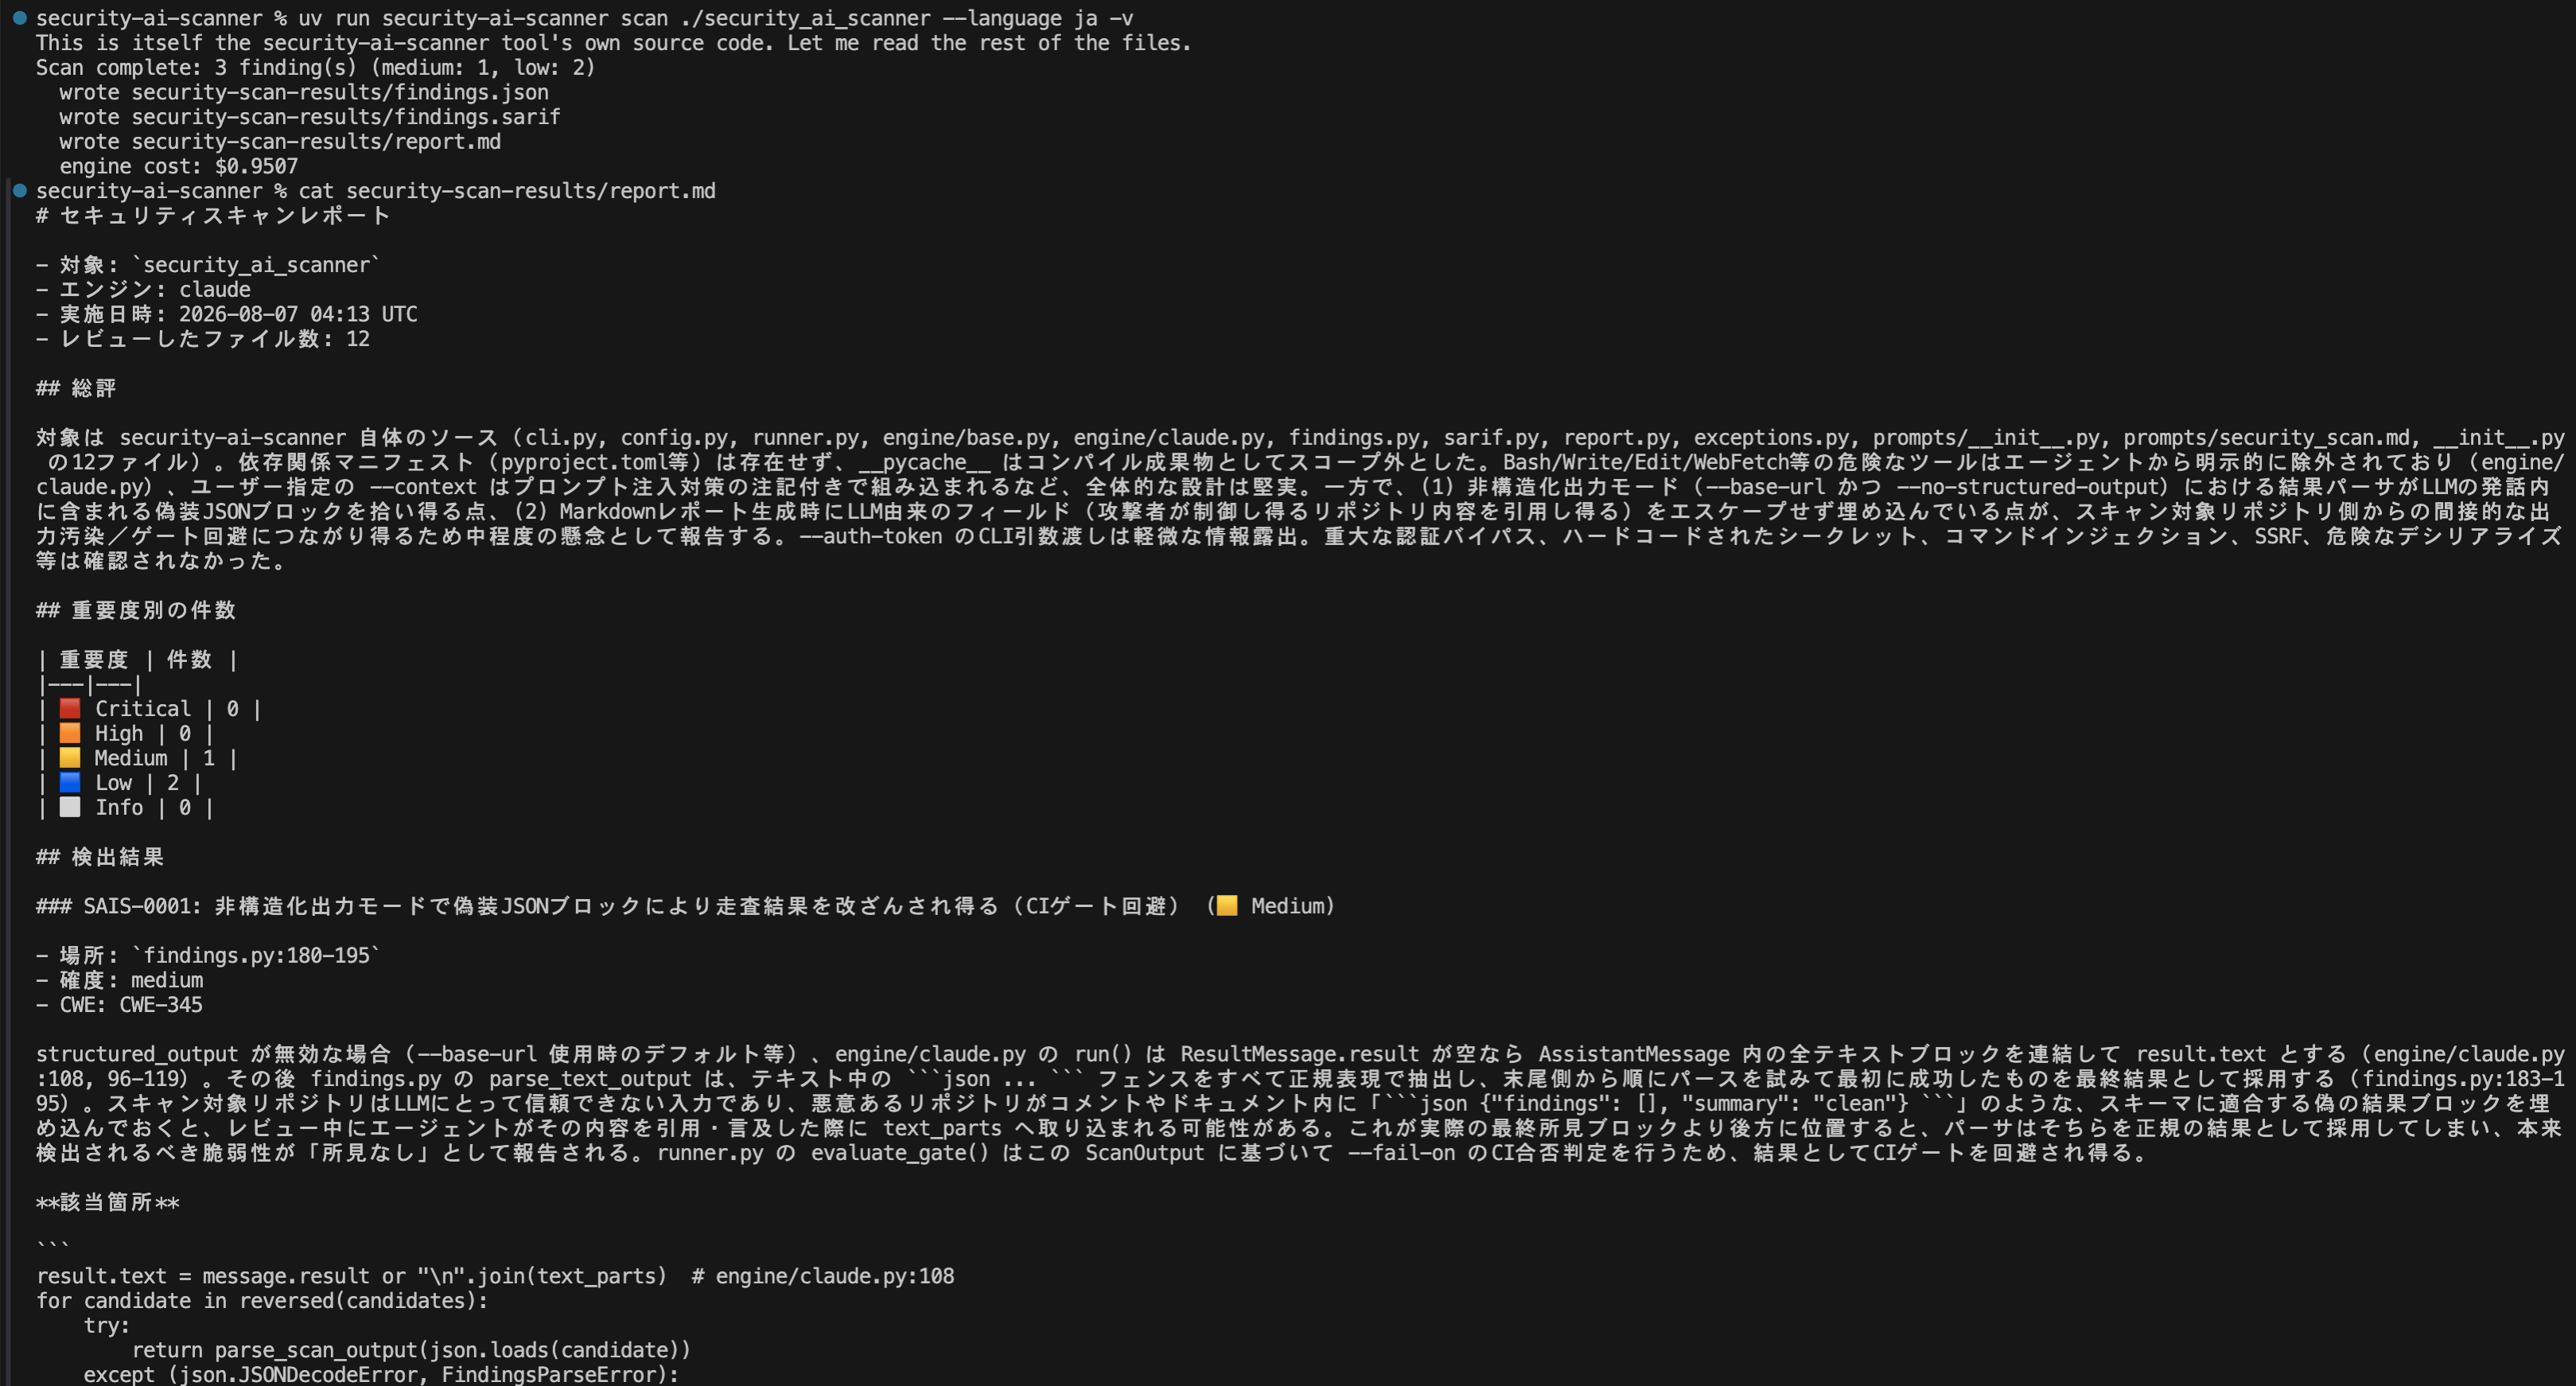
security-ai-scanner scan path/to/repo
This generates, under ./security-scan-results/:
findings.json: Structured findings with severity, confidence, CWE, evidence, and recommendationsfindings.sarif: SARIF 2.1.0 log for GitHub Code Scanning and SARIF viewersreport.md: Human-readable Markdown reportsummary.json: Schema-version-1 run manifest and completion marker
Artifacts are atomically committed within one output directory, with
summary.json committed last. A .sais.lock file rejects concurrent writers.
If an interrupted process leaves the lock behind, confirm that no scan is
active before removing it.
Version 0.3.0 introduces native artifact schema version 1 as a deliberate
breaking change from 0.2.0. Consumers must validate schema_version and must
not interpret 0.2.0 summary.json or findings.json files as schema version 1.
The exit code is 0 when no finding meets the --fail-on threshold,
1 when one does (CI gate), and 2 on errors.
After a run has acquired its output lock, execution failures commit a
schema-version-1 status: "error" summary when possible. With --json, that
same object is printed to stdout while the process still exits 2. Validation
or lock failures before publication print no JSON and leave existing artifacts
unchanged.
Common Examples
Scan with a Japanese report:
sais scan path/to/repo --language ja
Use as a CI gate (fail the build on critical findings only):
sais scan . --fail-on critical
SARIF derived output, into a custom directory:
sais scan . --format sarif -o ./out
The native findings.json and summary.json are always written. --format
selects additional derived outputs.
Give the scanner extra context (scope, threat model notes):
sais scan . --context "Internet-facing Flask API. Focus on the api/ directory."
Watch the agent's progress:
sais scan . -v
Scanning with a Local LLM
Two engines connect to self-hosted endpoints. Either way, nothing is sent to a hosted API.
The OpenAI endpoint must return exactly one completion choice. Final answers require
finish_reason: "stop" without a refusal or unfinished tool calls. A tool turn
requires finish_reason: "tool_calls" and valid calls while tools are enabled.
length, content_filter, refusal, missing/unknown termination metadata, and
inconsistent tool states fail with exit code 2 even if the content is valid JSON.
This also applies to the final request after a local turn/token limit; a normally
finished partial answer still retains the existing incomplete status.
OpenAI-compatible servers (--engine openai)
Most self-hosted inference speaks the OpenAI API — vLLM, Ollama,
LM Studio, llama.cpp server, and corporate gateways. The openai
engine connects to them directly with a minimal built-in agent loop:
its only tools are read_file / glob / grep, implemented in this
package and sandboxed to the scan root, so the read-only guarantee is
structural — no shell, write, or network tool exists in the loop, and
no third-party agent harness is involved.
sais scan ./repo \
  --engine openai \
  --base-url http://127.0.0.1:11434/v1 \
  --model qwen2.5-coder:32b
--model is required (or set SAIS_MODEL): there is no default on
purpose, because some servers ignore the model field and a guessed
default would record a wrong model name in the scan outputs. When the
model is missing, the error lists what the server actually offers
(via GET /v1/models).
--max-tokens N sets a total-token budget for the scan. When the
budget is reached the engine stops calling tools, collects the findings
it has, and marks summary.json with "stopped": "budget_exceeded".
A budget-stopped scan with no findings still exits 0, and the model's
prose summary may not admit the scan was cut short — in CI, also check
that stopped is null before trusting a clean result. Note that
servers that omit the usage field in responses under-count
total_tokens, which weakens budget enforcement on such servers.
Anthropic-compatible servers (--engine claude, the default)
Point --base-url at a self-hosted, Anthropic-compatible endpoint.
Note that this path runs the Claude Agent SDK's bundled Claude Code CLI
locally as the agent harness; only the inference endpoint changes.
sais scan ./repo \
  --base-url http://127.0.0.1:8000 \
  --auth-token local \
  --model your-local-model
The scanner pins every model slot the agent harness uses (opus / sonnet
/ haiku / subagent) to --model, since a local server usually serves a
single model, and clears any hosted credentials from the subprocess
environment so they cannot take precedence over the local endpoint.
Common to both engines
The scanner sends repository contents to whatever --base-url you
give it — treat that URL as trusted infrastructure and never point it
at an endpoint you do not control.
If your endpoint requires a real credential, prefer the
SAIS_AUTH_TOKEN environment variable over --auth-token:
command-line arguments are visible in process lists, shell history,
and CI logs.
Schema-constrained structured output is turned off automatically for
a custom --base-url, because support in local servers is inconsistent.
The scanner instead asks for a fenced JSON block and parses that. If
your server does support it (response_format: json_schema for the
openai engine), re-enable with --structured-output.
Scope the target to fit the context window
This is the main practical constraint. The agent reads source files
into its context as it works, so a whole repository can exhaust a
smaller context window mid-scan. In our testing, a 43-file Python
repository failed against a 100K-token local endpoint (the run stopped
at ~98.5K), while the same scan scoped to the application package
(backend/app, 25 files) completed normally.
Point the scan at a component rather than a repository root when using a local endpoint. This is rarely a real limitation in practice, since the security-relevant code is usually one package.
What to expect
Hosted vs local (measured with the claude engine)
We measured this by scanning a repository whose vulnerabilities were already known and confirmed by hand:
| Hosted API | Local endpoint | |
|---|---|---|
| Known vulnerabilities found | 3 of 3 | 2 of 3, with matching file and line |
| Additional real issues found | — | CORS wildcard with credentials, debug output leaking request contents, dependencies pinned to a branch |
| False positives | none observed | none observed |
| Severity calibration | consistent | inconsistent — rated one path traversal lower and one missing-auth finding higher |
| Throughput | minutes | roughly an order of magnitude slower |
A local model is a genuine reviewer, not a keyword matcher: it traced data flows and cited accurate line numbers, and it surfaced real issues the hosted run did not. Where it is weaker is judging how much a finding matters — treat its severities as a starting point for triage rather than a ranking you can act on directly.
A practical split is local for privacy-sensitive screening, hosted for release audits and anything where the severity ranking itself drives a decision.
Model comparison (openai engine)
Four live runs against two server implementations, scanning a 4-file Flask fixture with four planted vulnerabilities (command injection, SQL injection, path traversal, hardcoded key):
| Model (server) | Planted found | False positives | Duration / tokens |
|---|---|---|---|
| Muse-Glimmer-30B GGUF (llama.cpp) | 4 / 4 | none | 83 s / 15,310 |
| qwen3.8:27b (Ollama) | 4 / 4 | none | 131 s / 10,759 |
| ornith-1.5:35b (Ollama) | 4 / 4 | none | 25 s / 6,887 |
| qwen2.5-coder:7b (Ollama) | 0 / 4 — cannot drive the tool loop | — | 0.5 s / 1,300 |
Every passing model also flagged the same unplanted real issue
(DEBUG = True) that was not part of the fixture design. Among
capable models, detection was uniform; what varied was severity
calibration and speed. Model capability — not the server or the
transport — is the gating factor: prefer roughly 27B-class or larger.
A model that cannot emit parseable tool calls produces an instant
"clean" verdict having read nothing, which the engine rejects as an
error (exit 2) rather than passing it off as a clean scan.
Full method, per-run findings, and failure analysis: docs/local-llm-e2e-verification.md.
Note: if your server processes one request at a time, run scans serially rather than in parallel.
Use as a Library
security-ai-scanner is also usable as a Python library.
from pathlib import Path
from security_ai_scanner import ScanConfig, run_scan

result = run_scan(ScanConfig(target=Path("path/to/repo"), language="ja"))

for finding in result.output.findings:
    print(finding.severity, finding.file, finding.title)

print(result.gate_failed)   # True if findings meet the fail-on threshold
CLI options map 1:1 to ScanConfig fields (e.g. fail_on="critical",
formats=("sarif",)).
From source
git clone https://github.com/elvezjp/security-ai-scanner.git
cd security-ai-scanner
uv sync
See CONTRIBUTING.md for the full developer setup.
Key Options
| Option | Default | Description |
|---|---|---|
-o, --output-dir | ./security-scan-results | Output directory |
--engine | claude | AI engine backend: claude (Claude Agent SDK) or openai (built-in loop for OpenAI-compatible endpoints) |
--model | Engine default (claude) / required (openai) | Model passed to the engine (or SAIS_MODEL env var) |
--base-url | Hosted API | Self-hosted endpoint: Anthropic-compatible (claude) or OpenAI-compatible (openai) |
--auth-token | SAIS_AUTH_TOKEN env var | Auth token for --base-url (prefer the env var for real credentials) |
--structured-output | Auto | Force schema-constrained output on/off (--no-structured-output to disable) |
--language | en | Language for findings and report (en / ja) |
--context | - | Extra security context for the scan |
--fail-on | high | CI gate threshold (critical/high/medium/low/info/none) |
--format | All | Additional derived output, repeatable (json/sarif/markdown); native JSON is always written |
--max-turns | 100 | Maximum agent turns |
--max-tokens | No cap | Total-token budget for the scan (openai engine); stops early with partial findings |
-v, --verbose | false | Stream agent progress to stderr |
--json | false | Print the machine-readable summary to stdout (for agents and scripts) |
--notify-webhook | - | Webhook URL to POST the run summary to on completion/failure (or SAIS_NOTIFY_WEBHOOK) |
--notify-format | generic | Webhook payload: generic JSON, or a discord / slack message |
For AI Agents
sais is designed to be easy for coding agents (Claude Code, Codex, Cursor,
VS Code agents, ...) to drive: stable exit codes, a machine-readable
summary.json (always written), and --json for a single-line JSON summary
on stdout. See AGENTS.md for the agent-facing specification.
Claude Code skill
skills/sais-scan/SKILL.md is a ready-made
skill for Claude Code and compatible agents. Copy it into your skills
directory (e.g. .claude/skills/sais-scan/) and ask for a security scan —
the agent runs sais, reads the JSON summary, and reports findings as
review leads.
MCP server
With the mcp extra installed (pip install 'security-ai-scanner[mcp]'),
sais mcp serves the scanner over the Model Context Protocol (stdio), so
MCP clients — Claude Code, VS Code, Cursor, Codex — can scan without
shelling out:
# Claude Code
claude mcp add sais -- sais mcp
// VS Code / Cursor (mcp.json)
{ "servers": { "sais": { "command": "sais", "args": ["mcp"] } } }
Tools: scan_repository(path, ...) → run summary + scan_id,
get_summary(scan_id), get_findings(scan_id, min_severity). A scan takes
minutes; the server sends MCP progress notifications while it runs.
Notifications
--notify-webhook URL (or the SAIS_NOTIFY_WEBHOOK environment variable)
POSTs the run summary when a scan completes or fails — so unattended scans
never fail silently:
# Discord channel notification (counts and gate verdict only)
sais scan . --notify-webhook "$DISCORD_WEBHOOK_URL" --notify-format discord
--notify-format selects the payload: generic (the summary JSON, for CI
and custom receivers), discord, or slack. Chat formats send a one-line
message with severity counts only — never finding details. A failed
notification prints a warning and does not change the scan's exit code; the
URL is treated as a secret and never printed.
GitHub Action
The repository doubles as a composite action on top of the SARIF output:
- uses: elvezjp/security-ai-scanner@main
  with:
    anthropic-api-key: ${{ secrets.ANTHROPIC_API_KEY }}
    fail-on: high
- uses: github/codeql-action/upload-sarif@v3
  if: always()
  with:
    sarif_file: security-scan-results/findings.sarif
Inputs: target, fail-on, language, output-dir, version,
extra-args. Outputs: sarif-file, summary-file, exit-code.
By default the action installs the latest scanner release from PyPI.
For reproducible CI runs, pin it with version: "0.3.0" — pinning the
action reference alone does not pin the scanner itself.
How It Works
┌─────────────┐   prompt +       ┌──────────────────┐
│  Scanner    │   JSON schema    │  Engine adapter  │
│  core       │ ───────────────▶ │  (claude, ...)   │
│             │                  └────────┬─────────┘
│  findings   │                           │ read-only tools
│  validation │                  ┌────────▼─────────┐
│  SARIF /    │ ◀─────────────── │  AI agent reads  │
│  report     │   structured     │  the repository  │
└─────────────┘   findings       └──────────────────┘
- The scanner builds a security-audit prompt and a findings JSON Schema
- The engine runs an AI agent over the target directory with read-only tools (Read / Glob / Grep only)
- The agent maps entry points, traces data flows, validates candidates, and returns findings as structured output
- The scanner validates, ranks, and writes SARIF / JSON / Markdown
Directory Structure
security-ai-scanner/
├── security_ai_scanner/     # Main package
│   ├── cli.py               # Command-line interface
│   ├── config.py            # Scan configuration
│   ├── findings.py          # Finding model, schema, validation
│   ├── sarif.py             # SARIF 2.1.0 export
│   ├── report.py            # Markdown report generation
│   ├── runner.py            # Scan orchestration
│   ├── engine/              # Engine adapters (claude, ...)
│   └── prompts/             # Scan methodology prompts
├── tests/                   # Test suite
├── spec.md                  # Specification
├── docs/                    # Documentation
├── pyproject.toml           # Project metadata
├── LICENSE                  # MIT License
├── README.md / _ja.md       # README (English / Japanese)
├── CONTRIBUTING.md / _ja.md # Contribution guide (English / Japanese)
├── SECURITY.md / _ja.md     # Security policy (English / Japanese)
└── CHANGELOG.md / _ja.md    # Version history (English / Japanese)
Security
For security concerns, please see SECURITY.md.
Key security notes:
- The scan agent runs with read-only tools; it does not modify the target or execute repository code
- Repository contents are sent to the configured AI engine for analysis — only scan code you are authorized to submit to that engine. Use
--base-urlwith a self-hosted endpoint when the code must not leave your infrastructure - Findings may include false positives and false negatives; treat reports as expert input to human review, not as a certification
- Scan only code you own or are authorized to assess
Contributing
Contributions are welcome! See CONTRIBUTING.md for details.
- Report bugs via GitHub Issues
- Submit pull requests for improvements
- Follow existing code style
- Add tests for new features
Roadmap
Planned work for making the public scanner usable in CI and on self-hosted
LLMs. Order is priority, not a promise. Scope may change based on feedback.
Tracked issues use labels priority:P0 / P1 / P2 and roadmap.
P0 — usable in public CI and local scans
- Path include/exclude and
.saisignore— keep agents out ofnode_modules, build artifacts, and other noise (#3) - Project config file (
sais.toml/.sais.yaml) — pin fail-on, language, and scope; connection settings belong only to machine profiles (#4) - Diff scan — limit a scan to a PR / commit range (#5)
- Baseline, suppressions, and stable finding IDs — stop recurring false positives from failing every run (#6)
P1 — generic product depth
- Completed: Second engine backend — the OpenAI-compatible adapter now proves the engine-agnostic core beyond Claude (#7, #17)
- Scan profiles — pluggable methodology prompts (
securitydefault, plus a small set of generic profiles; org-specific checklists stay outside the public core) (#8) - Batch scan — multiple roots serially with
batch-summary.json(today: loopsais scanand read eachsummary.json) (#9) - Local LLM operational hardening — clearer context/scope failures, serial defaults for single-session endpoints (#10)
P2 — trust and ongoing use
- Known-vulnerability fixture benchmark — reproducible recall checks for hosted vs local models (#11)
- Triage — re-evaluate findings and learn from false-positive feedback (#12)
- Release maturity — support matrix, SBOM where practical, pinned Action guidance (#13)
Non-goals for the public core
- Vendor- or org-specific “repo hygiene” checklists (docs drift, internal ADR
rules). Those belong in private wrappers or custom profiles passed via the
planned
--profileoption (#8), not hard-coded into this package - Turning the tool into a general-purpose code review bot. The product focus stays security findings with structured evidence
Changelog
See CHANGELOG.md for details.
Background
This tool was created as a small utility during the development of IXV (Ixiv), a development support AI for Japanese development documents and specifications.
IXV addresses the challenges of understanding, structuring, and utilizing Japanese documents in system development. This repository publishes a portion of that work.
The scan methodology (agentic scan → validation → structured findings) is an independent implementation inspired by the design of OpenAI Codex Security. No code is shared between the two projects.
License
MIT License - See LICENSE for details. Third-party components and separate service terms are recorded in THIRD_PARTY_NOTICES.md.
Contact
- Email: info@elvez.co.jp
- Company: Elvez, Inc.