
mcp server
Intent
A programmable kernel DSL and MLIR compiler for GPU, CPU, and accelerator execution models
Set up
Runs on your computer. Pick your agent and operating system.
Before you start
- uv (`curl -LsSf https://astral.sh/uv/install.sh | sh`)
{
  "mcpServers": {
    "tianchen-ai-intent": {
      "command": "uvx",
      "args": [
        "intentdsl"
      ]
    }
  }
}
same format Cursor, GitHub Copilot CLI, Junie, JetBrains AI Assistant, Augment (Auggie CLI), Factory Droid, Kiro, Devin CLI +12
Values in angle brackets are placeholders. Restart Claude Desktop after editing its config.Claude Desktop docs
README
synced Oct 25, 2026IntentDSL
Write an operator algorithm once. Compile it for different execution models.
Documentation · Installation · Examples · MCP · Contributing
IntentDSL is a Python kernel language and an MLIR compiler for GPU, CPU, and accelerator programs. Authors describe tensor computations, logical domains, accesses, state, and explicit multi-kernel composition. Compiler passes form the physical program and lower it through Triton, cuTile, Mojo, Weft, or BANG C.
IntentDSL is a component of the Dongshan Community's TianChen AI Software Stack. This repository provides the language, compiler, examples, and usage documentation; the top-level repository maps the stack's components. Development is maintained on GitHub, with a Gitee mirror.
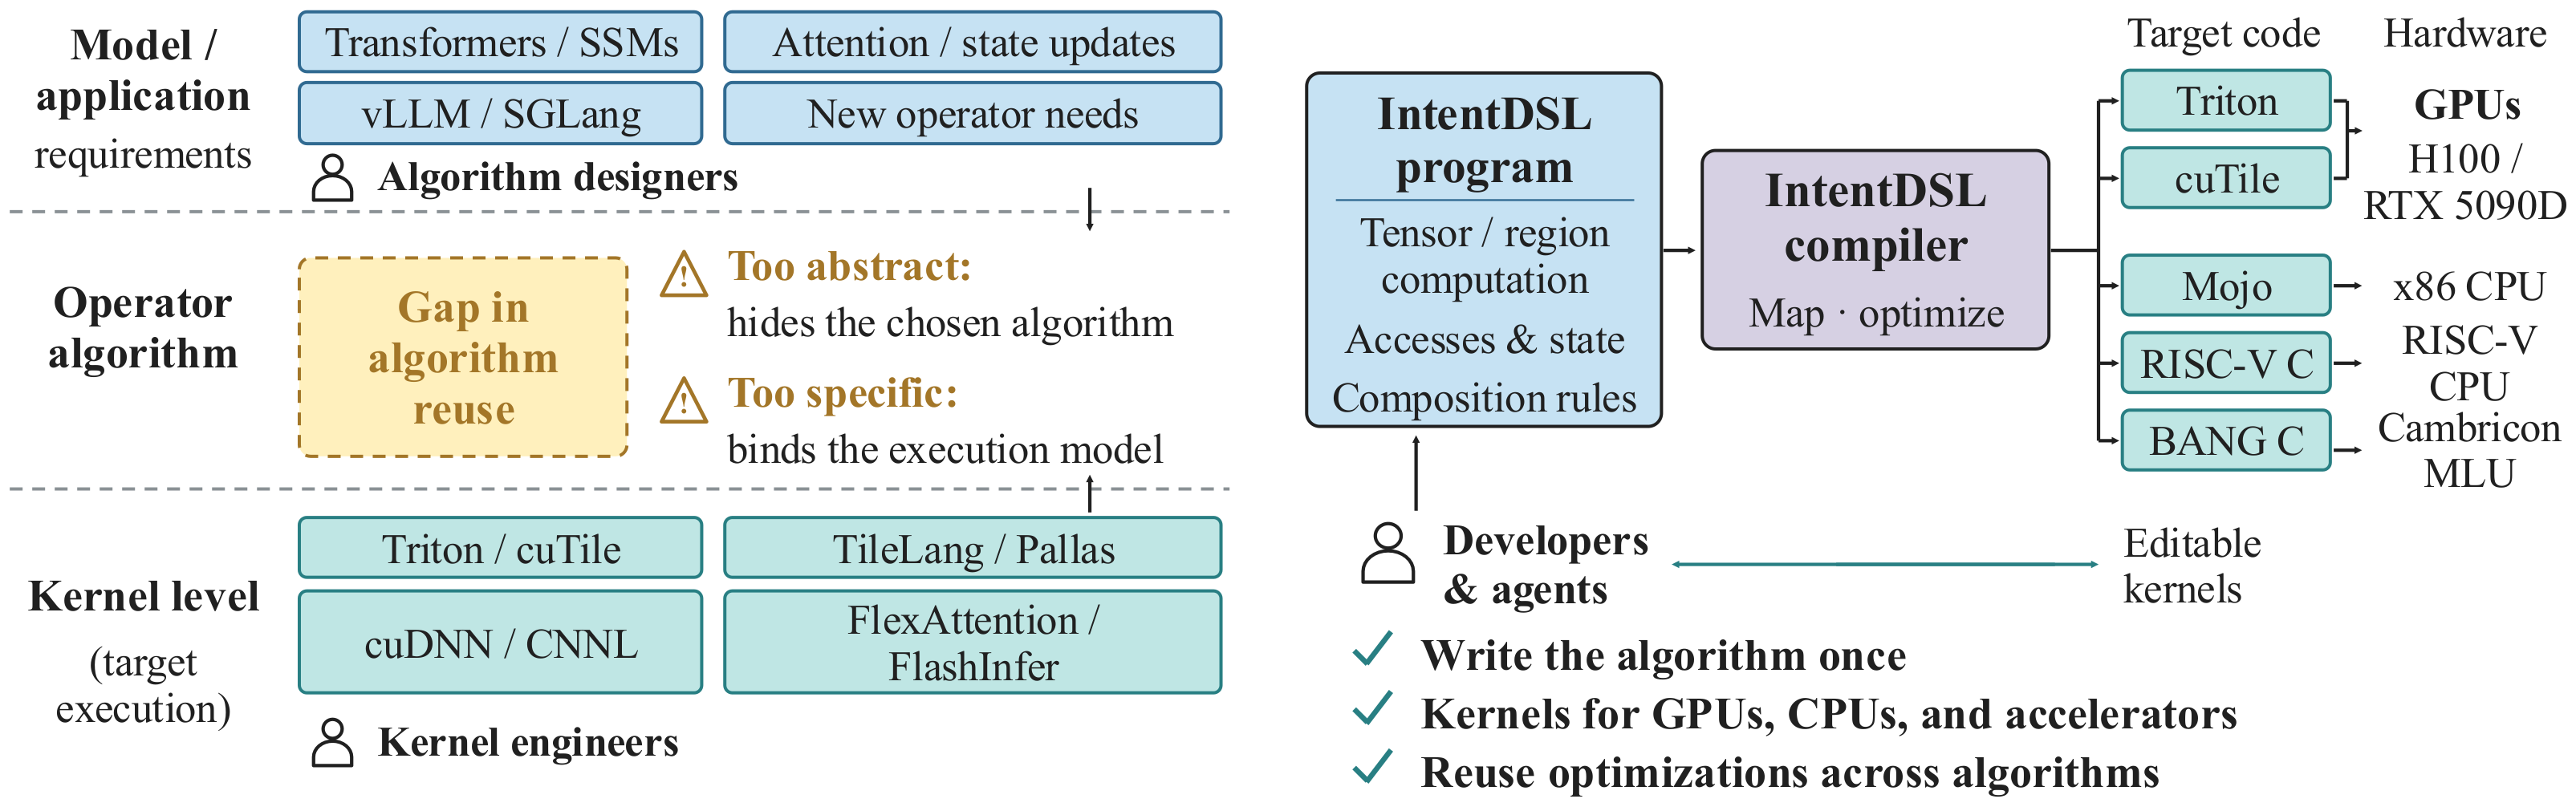
Original paper overview (PDF). Labels describe the paper's implementation paths; current provider entry points are listed below.
- Programmable algorithms: compose reductions, contractions, indexed access, control flow, and region computations inside a kernel.
- Reusable optimization: shared semantic analyses and execution-family passes organize computation, reuse, and storage; provider compilers perform their own layout and instruction lowering.
- Ordinary Python calls: compile once, pass tensors or native buffers, and inspect the generated source, IR, and selected configuration.
Get started
The GPU setup uses Linux, Python 3.10–3.12, and an NVIDIA GPU. A prebuilt wheel installs the compiler without an LLVM/MLIR SDK. See the installation guide for other backends and source-build prerequisites.
Install with pip
Install the compiler from PyPI. The optional extras add the MCP servers and portable example inputs:
python3 -m venv .venv-triton
source .venv-triton/bin/activate
python -m pip install 'intentdsl[manual,examples]'
intent setup --target triton
intent doctor --target triton
The wheel targets Linux x86-64 with glibc 2.35 or newer. It includes the native compiler, optimizer, profiles, manual, and compiler runtime libraries, so installation needs no LLVM/MLIR SDK. Backend SDKs and drivers are selected separately. The base compiler installs with pip install intentdsl; its Python import is intent. Downloadable wheels are also available in the GitHub preview.
Install from source
git clone https://github.com/Tianchen-ai/Intent.git
cd Intent
python3 environment/install.py --backend triton --venv .venv-triton --examples
source .venv-triton/bin/activate
intent doctor --target triton
python -m intent.examples softmax --backend triton
Source builds need CMake, Ninja, a C++17 compiler, and the LLVM/MLIR 20 C++ SDK. The script builds and installs the compiler and Python package, then installs the chosen backend. Build artifacts stay outside the checkout. Use --backend cutile --venv .venv-cutile for cuTile in a separate environment. Installation covers SDK packages, external CPU/MLU toolchains, and environment/build.py for building distributable wheels.
Write and call a kernel
Save this as a Python file and run it in the installed Triton environment. It uses the same algorithm as the ReLU example.
import torch
import intent
import intent.language as I


@intent.kernel
def relu(
    x: I.In[I.f16, ("M", "N")],
    output: I.Out[I.f16, ("M", "N")],
):
    M, N = x.shape
    columns = I.domain(0, N)
    for row in I.parallel(I.domain(0, M)):
        output[row, columns] = I.maximum(x[row, columns], I.cast(0.0, I.f16))


artifact = intent.jit(relu, backend="triton")
x = torch.randn((64, 1024), device="cuda", dtype=torch.float16)
y = artifact.run(x)
print(y.shape, y.dtype, y.device)
The kernel describes logical rows and columns. Compiler passes choose physical ownership, blocking, traversals, and storage. The target is selected on the host; the kernel does not branch on the backend.
intent.jit creates a reusable local callable. Choose the backend explicitly; actual input buffers determine the local device and its capabilities. First use performs compilation and necessary tuning; subsequent calls reuse the artifacts while binding their own buffers. artifact.run(...) allocates declared Out tensors, while artifact(...) accepts explicit outputs. Explicit generation and export remain available through intent.generate and intent.compile.
GPU and Mojo artifacts also provide artifact.as_torch_op("your_project::name") for opaque PyTorch custom operators and torch.compile integration. Authors register their own backward; the compiler preserves explicit kernel and host composition. See the framework examples.
Explore 30 complete programs
The installed intent.examples package covers attention, recurrent state, normalization, matrix and quantized contractions, sparse access, scans, and mutable updates. It owns one copy of each algorithm and its explicit host composition.
python -m intent.examples --list
python -m intent.examples attention --backend triton
python -m intent.examples paged_decode --backend cutile
intent-bench check --suite mainline --backend triton --stage source --env local-gpu
| Provider | Execution route |
|---|---|
| Triton / cuTile | NVIDIA GPU; PyTorch tensor and stream integration |
| Mojo | x86 CPU; external Mojo compiler |
| Weft | RISC-V local JIT; native ISA, VLEN and CPU capabilities discovered through Weft |
| BANG C | Cambricon MLU; external NeuWare SDK and compatible device |
Generation, native compilation, and execution are separate stages. Backend coverage depends on the program's operations, types, effects, and selected hardware. The examples guide describes inputs, complete calls, and target options.
Optional operator benchmarks
The independent intentdsl_bench checkout owns comparisons, baselines and historical
evaluation material. With that project checked out beside IntentDSL:
python -m pip install -e ../intentdsl_bench
intent-bench check --intent-root . --suite mainline --backend triton
intent-bench run softmax --impl triton,cutile,intent:triton,intent:cutile --intent-root . --device cuda:0
The default result is median latency; throughput can be requested separately. The compiler does not depend on the benchmark package.
How the compiler is organized
Passes consume typed semantics, def-use, coordinate relations, effects, and target capabilities. Execution decisions live in the current MLIR program. GPU, CPU, and DSA can reuse semantic knowledge while retaining their own execution and storage models.
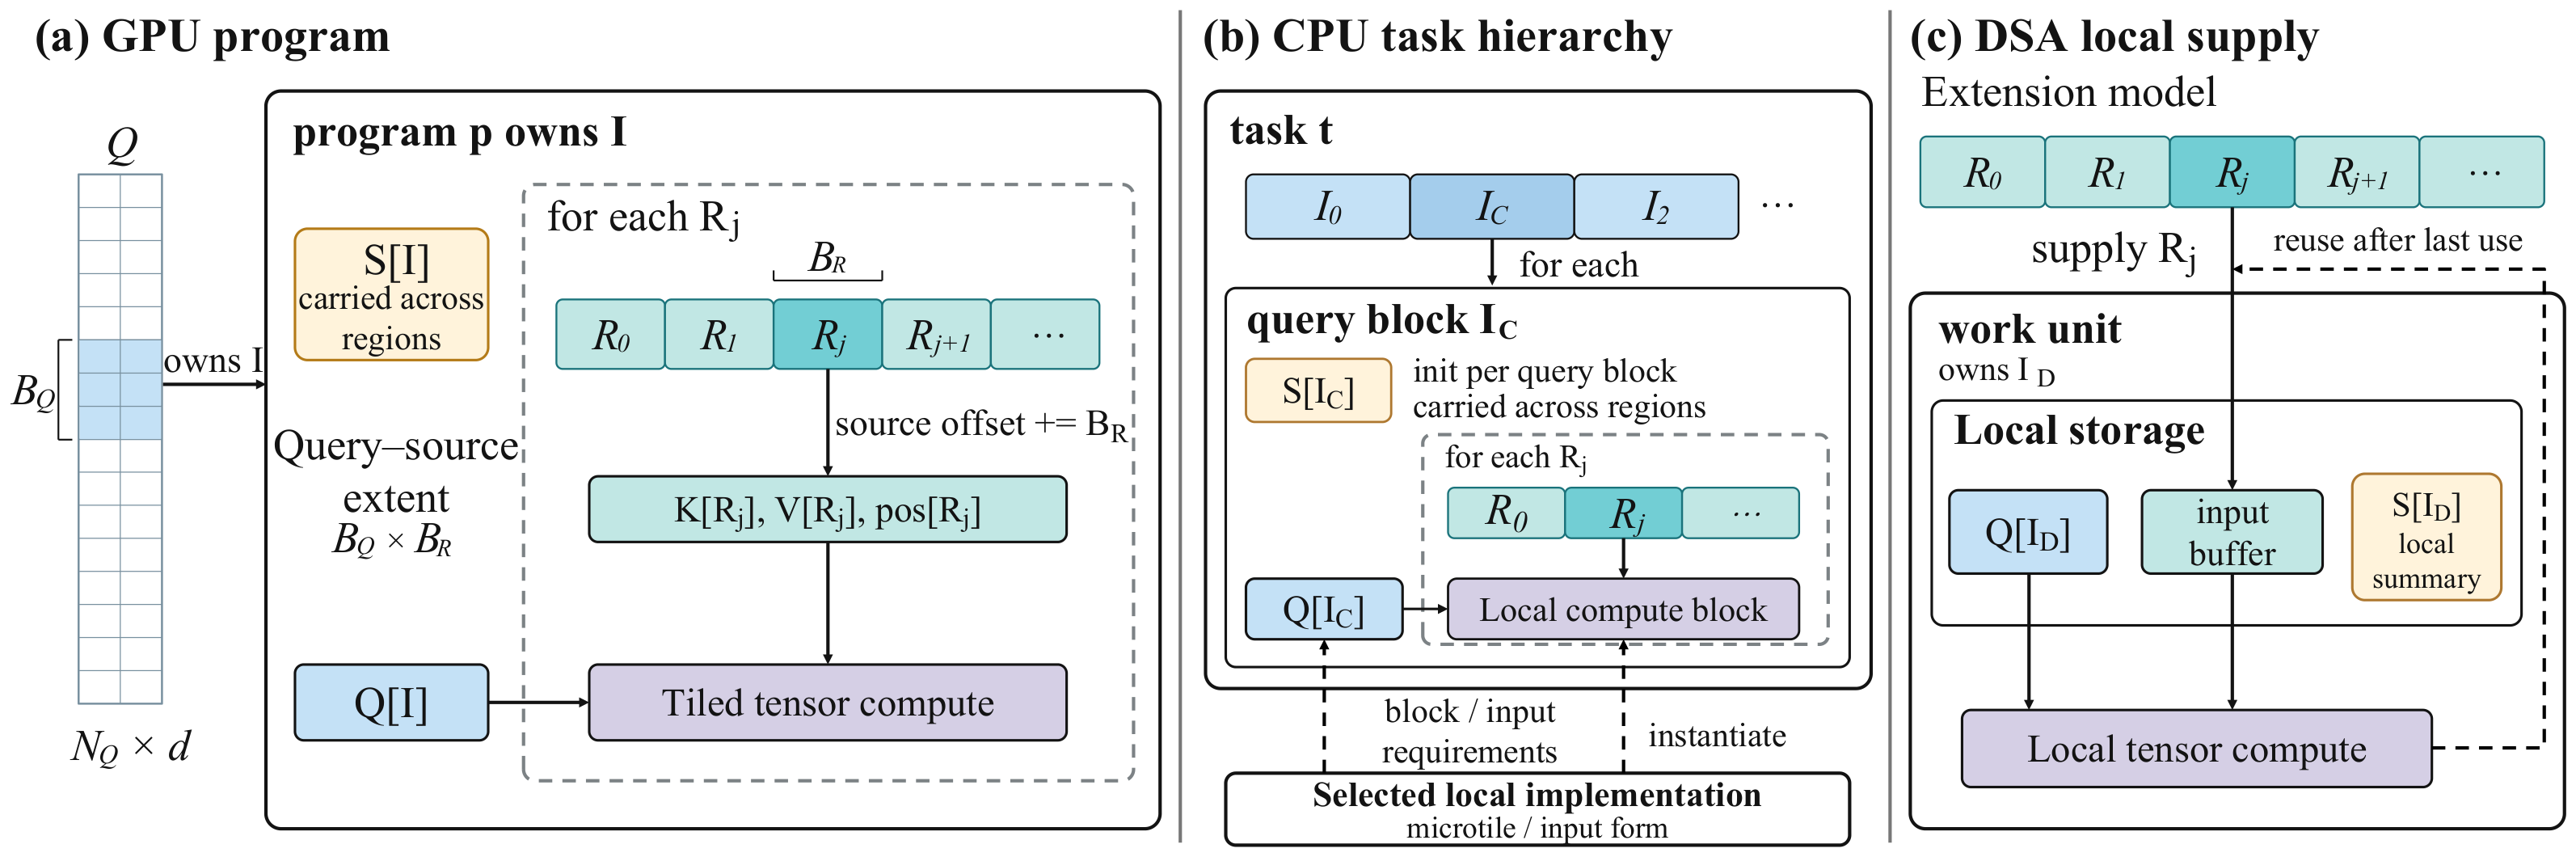
Original execution-construction figure (PDF): each execution model assigns query ownership and carries state across source regions. CPU implementation requirements shape local blocks; DSA dependencies govern input-buffer reuse.
Read the language manual, compiler specification, or contribution guide for the relevant entry point.
Performance across execution models
The following original paper figures compare complete operators with target-written implementations. Speedup is reference latency / generated latency; higher is better. Median operator latency includes preparation and required layout materialization, and excludes compilation, JIT, and tuning. These are historical paper measurements, not a new evaluation of the current package or the 30 product programs.
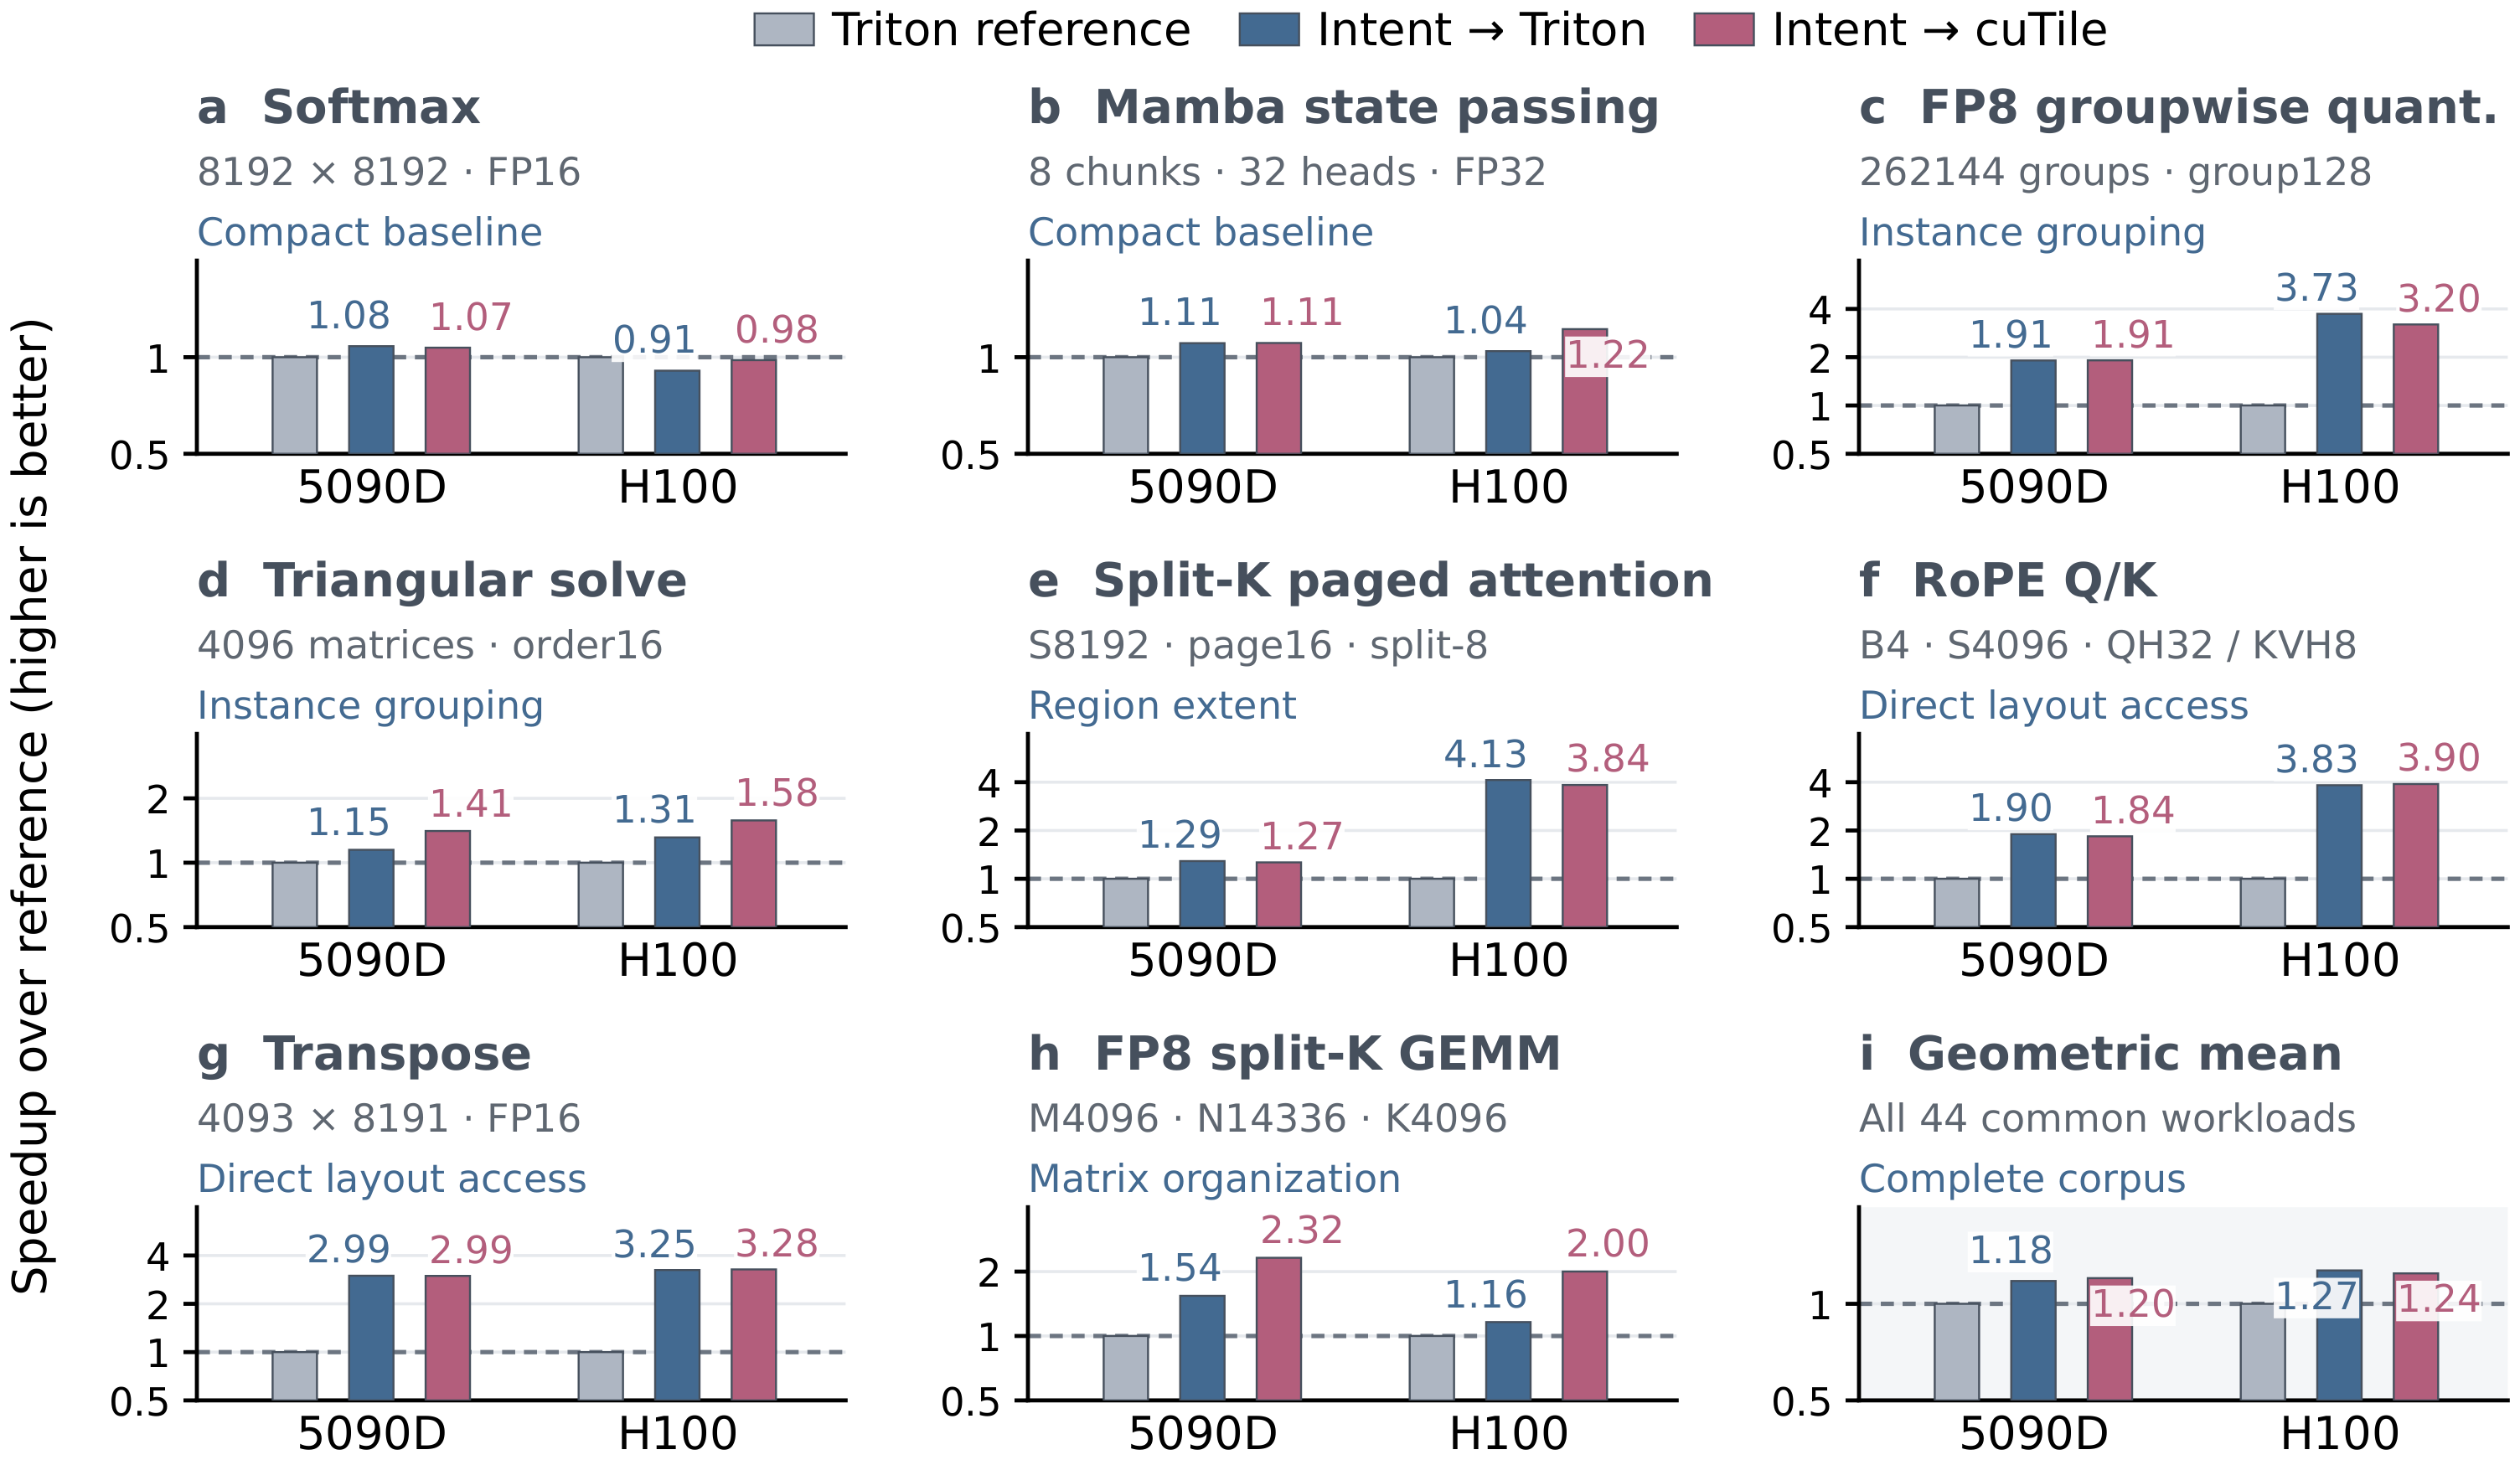
GPU (PDF): eight representative workloads and the geometric mean of all 44 common workloads. For each workload, the generated Triton and cuTile targets share the authored DSL algorithm, input scale, and external dtype. Representative shapes and precisions are labeled in the original figure; the gray bars are the paper's Triton references.
| x86 CPU · 7 native comparisons | MLU370 · 6 library comparisons |
|---|---|
| Original PDF | Original PDF |
CPU: generated Mojo programs against five Modular/MAX and two independent Mojo references, using eight physical x86 cores within one NUMA node. MLU: generated BANG C programs against CNNL/CNNL Extra/TMO, using MLU370 and CNCC/CNRT. Each comparison follows its paper workload's shapes, precision, outputs, and tolerance; these charts show per-workload ratios, not geometric means. Figure sources record the measurement scope.
Use with an agent
MCP has a dedicated directory and setup guide. Both stdio servers ship with the manual package extra:
| Command | Responsibility |
|---|---|
intent-manual | Read-only language contracts, API declarations, and minimal syntax fragments |
intent-compiler-mcp | Compile a supplied program, inspect the environment, optimize supplied IR, and read artifacts |
Start with read(id="doc/dsl/authoring.en.md") and api(name="intent.compile") in the manual. Enable the compiler server when the agent should compile a supplied Python program. It uses the same compiler as the CLI; importing a program executes its ordinary top-level Python.
Inspect compilation
intent compile python/intent/examples/kernels/normalization/softmax.py:stable_softmax_f16 \
  --stage kir --json
intent compile python/intent/examples/kernels/normalization/softmax.py:stable_softmax_f16 \
  --target triton --json
The CLI reports the actual compilation stage and artifact paths. In Python, use artifact.source, artifact.mlir, and artifact.cache_directory. Source generation and KIR inspection do not actively launch the selected kernel. See the usage guide for installed tools and diagnostics.
Contribute
Start with CONTRIBUTING.md for setup, compiler modules, pass contributions, and focused verification. Questions and reproducible problems belong in GitHub issues.
IntentDSL is licensed under Apache-2.0. Bundled third-party components retain their own notices and licenses.